

Is this your AI tool? Claim it today.
Verify ownership, manage your profile, and unlock growth features.
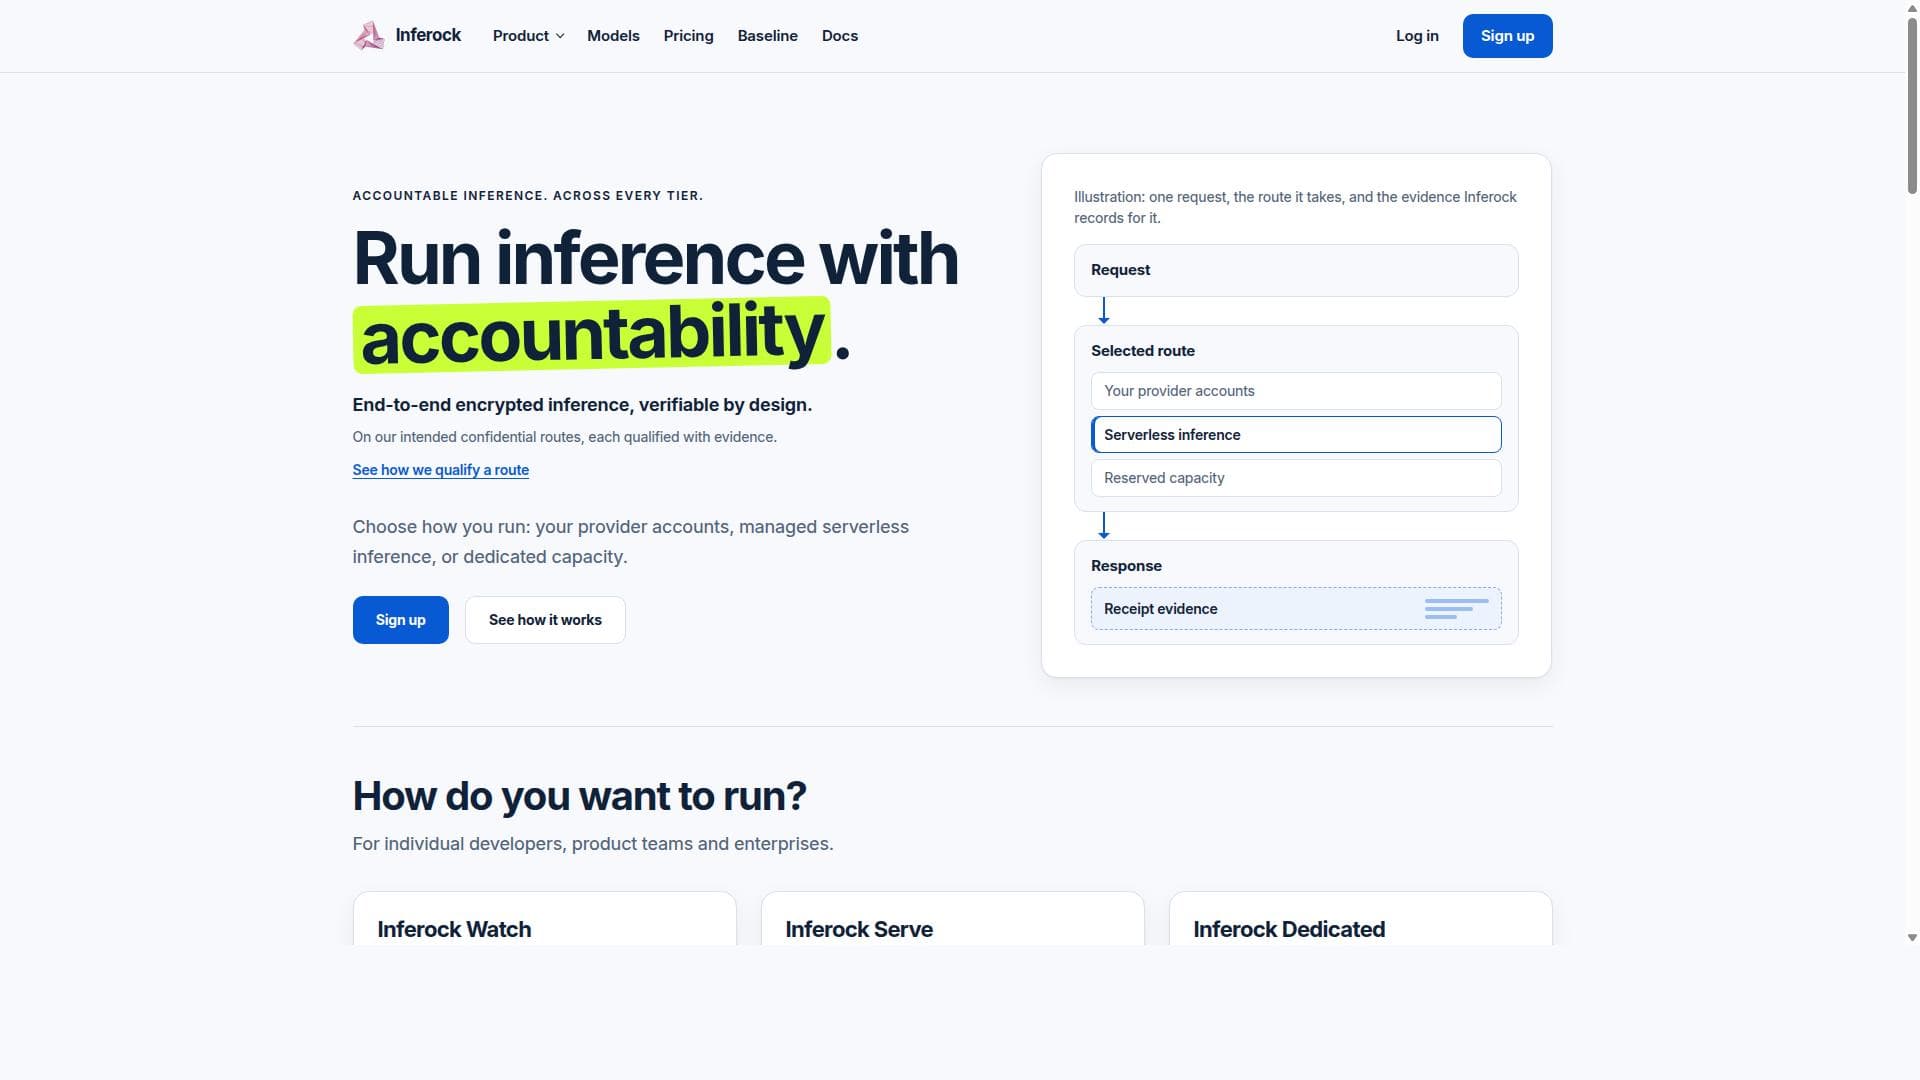
Inferock delivers secure, verifiable large language model inference with unmatched accountability, including per-call receipts and encrypted confidential routes. Ideal for developers and enterprises demanding transparent, trustworthy AI inference, it offers flexible deployment options from provider accounts to dedicated capacity.

Description
Get free signup credits to use all available models on Inferock. Bring your own keys: run your OpenAI, Claude or Gemini accounts, see where calls fail and what they cost, and get credits back on eligible failed calls. Serverless: pay-per-token LLM inference. Get signup credits to start using.
Detailed Description
Inferock is a cutting-edge AI tool designed to provide reliable and accountable large language model (LLM) inference services. Its core purpose is to enable users to run LLM inference workloads with full transparency, verifiable evidence, and robust accountability mechanisms. Unlike typical inference platforms, Inferock emphasizes end-to-end encrypted inference that is verifiable by design, ensuring that every inference call is securely processed on confidential routes. This approach guarantees data privacy and integrity, making Inferock a trustworthy choice for sensitive and mission-critical AI applications. At the heart of Inferock’s offering are several key features that set it apart from conventional LLM inference providers. First, it generates per-call receipts and detailed loss reporting, allowing users to audit each inference request and response thoroughly. This level of accountability ensures that users can verify the correctness and performance of their inference calls. Additionally, Inferock offers bounded service credits for eligible objective failures under agreed terms, providing a safety net and financial assurance if the service does not meet predefined performance standards. Inferock supports multiple deployment options tailored to different user needs. Users can run inference workloads using their own provider accounts through Inferock Watch, leverage managed serverless inference with Inferock Serve, or opt for dedicated capacity with Inferock Dedicated. This flexibility allows individual developers, product teams, and enterprises to choose the setup that best fits their scale, control, and compliance requirements. The platform also features independent measurement and monitoring of inference performance, ensuring unbiased verification of service quality. Furthermore, Inferock’s prepay billing option for serverless inference eliminates the need for users to provide provider API keys, simplifying onboarding and enhancing security. The tool is ideal for organizations and developers who require trustworthy, auditable LLM inference with strong privacy guarantees. Use cases include enterprises handling confidential data, AI product teams needing transparent cost and performance tracking, and developers seeking accountable serverless inference without managing infrastructure. Inferock’s verifiable encrypted inference routes make it particularly suitable for regulated industries and applications where data confidentiality and service accountability are paramount. Regarding pricing, Inferock offers different plans aligned with its deployment modes. Inferock Watch is free to use with users’ own provider keys, providing cost visibility and performance insights without additional fees. Inferock Serve offers managed serverless inference with a prepay billing model, removing the need for API keys and simplifying cost management. Inferock Dedicated provides reserved capacity with agreed pricing, service levels, and commitments, catering to high-demand enterprise workloads. Detailed pricing information is available on their website, allowing users to select plans that match their usage patterns and budget. Compared to alternatives, Inferock stands out by combining encrypted, verifiable inference with comprehensive accountability features such as per-call receipts and loss reporting. Many competing platforms offer inference services but lack transparent auditing or verifiable evidence of service quality. Inferock’s unique approach to confidential routes and independent performance measurement ensures users can trust the results and hold providers accountable. This makes it a superior choice for users prioritizing security, compliance, and reliability over generic inference offerings. However, potential users should consider that Inferock’s advanced accountability and encryption features may introduce additional complexity compared to simpler inference APIs. Organizations with minimal compliance requirements or low-risk applications might find more straightforward solutions sufficient. Additionally, while Inferock supports multiple deployment modes, users need to evaluate which setup aligns best with their technical capabilities and operational preferences. Overall, Inferock is a powerful platform for those who need verifiable, secure, and accountable LLM inference at scale.
Tool Features
- End-to-end encrypted inference with verifiable evidence
- Per-call receipts and loss reporting for accountability
- Multiple deployment options: provider accounts, serverless inference, dedicated capacity
- Service credits for eligible failures under agreed terms
- Independent measurement and monitoring of inference performance
- Prepay billing option with no provider API key required for serverless inference
- Dedicated capacity with agreed price, commitment, and service level
Description
Inferock delivers secure, verifiable large language model inference with unmatched accountability, including per-call receipts and encrypted confidential routes. Ideal for developers and enterprises demanding transparent, trustworthy AI inference, it offers flexible deployment options from provider accounts to dedicated capacity.
Get free signup credits to use all available models on Inferock. Bring your own keys: run your OpenAI, Claude or Gemini accounts, see where calls fail and what they cost, and get credits back on eligible failed calls. Serverless: pay-per-token LLM inference. Get signup credits to start using.
Detailed Description
Inferock is a cutting-edge AI tool designed to provide reliable and accountable large language model (LLM) inference services. Its core purpose is to enable users to run LLM inference workloads with full transparency, verifiable evidence, and robust accountability mechanisms. Unlike typical inference platforms, Inferock emphasizes end-to-end encrypted inference that is verifiable by design, ensuring that every inference call is securely processed on confidential routes. This approach guarantees data privacy and integrity, making Inferock a trustworthy choice for sensitive and mission-critical AI applications. At the heart of Inferock’s offering are several key features that set it apart from conventional LLM inference providers. First, it generates per-call receipts and detailed loss reporting, allowing users to audit each inference request and response thoroughly. This level of accountability ensures that users can verify the correctness and performance of their inference calls. Additionally, Inferock offers bounded service credits for eligible objective failures under agreed terms, providing a safety net and financial assurance if the service does not meet predefined performance standards. Inferock supports multiple deployment options tailored to different user needs. Users can run inference workloads using their own provider accounts through Inferock Watch, leverage managed serverless inference with Inferock Serve, or opt for dedicated capacity with Inferock Dedicated. This flexibility allows individual developers, product teams, and enterprises to choose the setup that best fits their scale, control, and compliance requirements. The platform also features independent measurement and monitoring of inference performance, ensuring unbiased verification of service quality. Furthermore, Inferock’s prepay billing option for serverless inference eliminates the need for users to provide provider API keys, simplifying onboarding and enhancing security. The tool is ideal for organizations and developers who require trustworthy, auditable LLM inference with strong privacy guarantees. Use cases include enterprises handling confidential data, AI product teams needing transparent cost and performance tracking, and developers seeking accountable serverless inference without managing infrastructure. Inferock’s verifiable encrypted inference routes make it particularly suitable for regulated industries and applications where data confidentiality and service accountability are paramount. Regarding pricing, Inferock offers different plans aligned with its deployment modes. Inferock Watch is free to use with users’ own provider keys, providing cost visibility and performance insights without additional fees. Inferock Serve offers managed serverless inference with a prepay billing model, removing the need for API keys and simplifying cost management. Inferock Dedicated provides reserved capacity with agreed pricing, service levels, and commitments, catering to high-demand enterprise workloads. Detailed pricing information is available on their website, allowing users to select plans that match their usage patterns and budget. Compared to alternatives, Inferock stands out by combining encrypted, verifiable inference with comprehensive accountability features such as per-call receipts and loss reporting. Many competing platforms offer inference services but lack transparent auditing or verifiable evidence of service quality. Inferock’s unique approach to confidential routes and independent performance measurement ensures users can trust the results and hold providers accountable. This makes it a superior choice for users prioritizing security, compliance, and reliability over generic inference offerings. However, potential users should consider that Inferock’s advanced accountability and encryption features may introduce additional complexity compared to simpler inference APIs. Organizations with minimal compliance requirements or low-risk applications might find more straightforward solutions sufficient. Additionally, while Inferock supports multiple deployment modes, users need to evaluate which setup aligns best with their technical capabilities and operational preferences. Overall, Inferock is a powerful platform for those who need verifiable, secure, and accountable LLM inference at scale.
Frequently Asked Questions
What is Inferock?
Inferock is an AI platform that provides reliable and accountable large language model (LLM) inference services with end-to-end encryption, verifiable evidence, and detailed performance reporting to ensure transparency and trust in AI workloads.
How much does Inferock cost?
Inferock offers different pricing models depending on the deployment option: Inferock Watch is free when using your own provider keys, Inferock Serve uses a prepay billing model without requiring provider API keys, and Inferock Dedicated provides reserved capacity with agreed pricing and service levels. Detailed pricing is available on their website.
Who is Inferock best for?
Inferock is best suited for individual developers, product teams, and enterprises that require secure, auditable, and accountable LLM inference—especially those handling sensitive data or needing verifiable service quality and compliance.
What are the main features of Inferock?
Key features include end-to-end encrypted inference with verifiable evidence, per-call receipts and loss reporting, multiple deployment options (provider accounts, serverless inference, dedicated capacity), service credits for eligible failures, independent performance monitoring, and a prepay billing option without needing provider API keys.
Does Inferock offer a free trial?
Inferock Watch, which allows you to connect your own provider keys and monitor inference performance, is free to use. This enables users to try out the platform’s accountability features without cost.
What integrations does Inferock support?
Inferock integrates with major LLM providers through user-connected accounts and supports serverless and dedicated inference deployments. It also offers open-source tools like inferock-bench for local cost tracking and monitoring across providers such as OpenAI, Anthropic, Gemini, and OpenRouter.
How does Inferock work?
Inferock routes inference requests through confidential, encrypted channels and generates per-call receipts that provide verifiable evidence of each request’s processing. Users can choose to run inference via their own provider accounts, managed serverless infrastructure, or dedicated reserved capacity, with independent monitoring ensuring accountability and performance transparency.
Socials
Use ToolReviews
No reviews yet. Be the first to share your experience.