

这是您的 AI 工具吗?立即认领。
验证所有权、管理资料,并解锁增长功能。
Weave Router is an open-source tool that smartly routes prompts to the cheapest capable large language model, cutting inference costs by up to 60% without sacrificing quality. Ideal for developers and businesses seeking rapid deployment and efficient LLM cost management, it offers a transparent, customizable solution to optimize AI spending.

描述
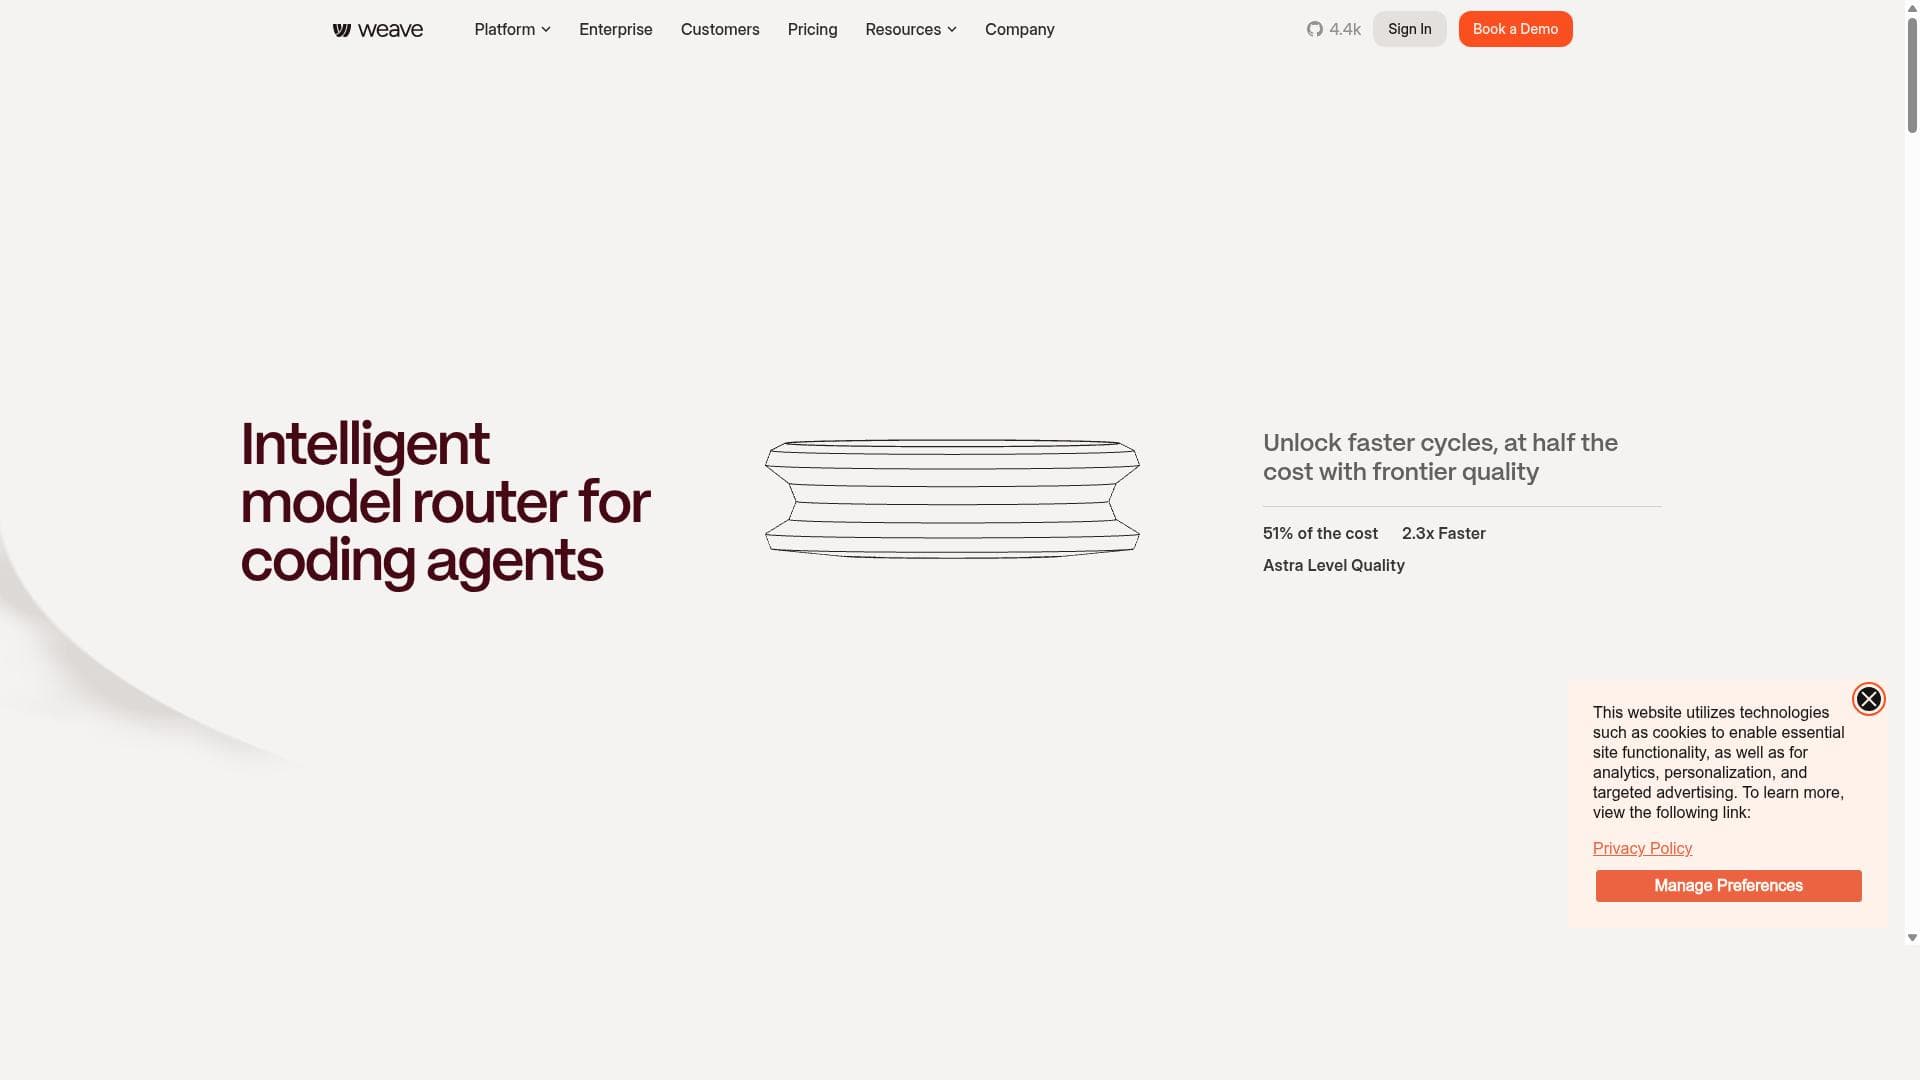
Use Claude models in Codex and GPT models in Claude Code on your existing plans, routed to whichever has quota left. Weave Router 2.0 routes each coding agent request to the cheapest model that can get it right. On Terminal-Bench 4.0 and SWE-Atlas it matches GPT-6 Astra at half the cost, 2x faster. Powered by a new classifier scores task complexity and ache-aware switching that only moves when savings beat the rebuild cost.
详细描述
Weave Router is an innovative open-source tool designed to optimize the cost efficiency of large language model (LLM) inference. Its core purpose is to intelligently route every prompt to the most cost-effective model that can still deliver the required quality and performance. By doing so, it achieves significant cost reductions—typically between 30% to 60%—without compromising the output quality. This makes Weave Router an essential solution for organizations and developers who rely heavily on LLMs but want to manage their expenses more effectively. The tool can be deployed live within a day, enabling rapid integration into existing workflows and immediate cost savings. The key features of Weave Router revolve around its smart routing mechanism. It evaluates each incoming prompt and dynamically selects the cheapest available model capable of handling the task, ensuring that users do not overpay for unnecessarily powerful or expensive models. This routing logic is the cornerstone of its cost-saving capabilities. Being open source, Weave Router offers transparency and flexibility, allowing users to customize and extend its functionality to fit their specific needs. Its quick deployment timeline—live within a day—means minimal setup time and fast realization of benefits. Additionally, the tool supports seamless integration into existing LLM infrastructure, making it adaptable for various environments and use cases. Weave Router is best suited for businesses, startups, and developers who utilize multiple LLMs or rely on high volumes of AI-driven text generation, natural language understanding, or conversational AI. It is particularly valuable for teams looking to optimize their AI budgets while maintaining consistent output quality. Use cases include customer support automation, content generation, data analysis, and any scenario where LLM inference costs can quickly escalate. By routing prompts to the most cost-effective model, organizations can scale their AI usage sustainably without sacrificing performance. Regarding pricing, Weave Router is open source, which means there are no licensing fees to use the software itself. Users only pay for the underlying LLM API calls or infrastructure costs associated with the models they choose to route to. This model allows for maximum cost control and transparency. Since it is open source, there are no proprietary pricing tiers, making it accessible to a wide range of users from individual developers to large enterprises. Compared to alternatives, Weave Router stands out due to its open-source nature and its focus on cost optimization through intelligent prompt routing. While many LLM management tools focus on monitoring or analytics, Weave Router actively reduces costs by selecting the cheapest capable model for each prompt. This dynamic routing approach is more proactive and financially beneficial than static model selection or manual cost management. Its rapid deployment capability also gives it an edge over more complex or proprietary solutions that require lengthy integration. However, there are some considerations to keep in mind. Since Weave Router depends on the availability and capability of multiple LLMs, its effectiveness relies on having access to a diverse set of models with varying cost and performance profiles. Organizations without multiple model options may not realize the full cost savings. Additionally, while the tool maintains output quality by routing to capable models, there may be edge cases where subtle differences in model behavior could affect results. Users should thoroughly test and validate the routing configurations in their specific context. Lastly, as an open-source project, support and updates depend on the community and maintainers, which may require some technical expertise to manage effectively. In summary, Weave Router is a powerful, cost-saving tool for managing LLM inference expenses through smart prompt routing. Its open-source availability, rapid deployment, and significant cost reduction potential make it an attractive choice for anyone looking to optimize their AI model usage without compromising quality.
工具功能
- Sends every prompt to the cheapest model that can do the job
- Reduces LLM inference costs by 30-60%
- Open source
- Live deployment in a day
描述
Weave Router is an open-source tool that smartly routes prompts to the cheapest capable large language model, cutting inference costs by up to 60% without sacrificing quality. Ideal for developers and businesses seeking rapid deployment and efficient LLM cost management, it offers a transparent, customizable solution to optimize AI spending.
Use Claude models in Codex and GPT models in Claude Code on your existing plans, routed to whichever has quota left. Weave Router 2.0 routes each coding agent request to the cheapest model that can get it right. On Terminal-Bench 4.0 and SWE-Atlas it matches GPT-6 Astra at half the cost, 2x faster. Powered by a new classifier scores task complexity and ache-aware switching that only moves when savings beat the rebuild cost.
详细描述
Weave Router is an innovative open-source tool designed to optimize the cost efficiency of large language model (LLM) inference. Its core purpose is to intelligently route every prompt to the most cost-effective model that can still deliver the required quality and performance. By doing so, it achieves significant cost reductions—typically between 30% to 60%—without compromising the output quality. This makes Weave Router an essential solution for organizations and developers who rely heavily on LLMs but want to manage their expenses more effectively. The tool can be deployed live within a day, enabling rapid integration into existing workflows and immediate cost savings. The key features of Weave Router revolve around its smart routing mechanism. It evaluates each incoming prompt and dynamically selects the cheapest available model capable of handling the task, ensuring that users do not overpay for unnecessarily powerful or expensive models. This routing logic is the cornerstone of its cost-saving capabilities. Being open source, Weave Router offers transparency and flexibility, allowing users to customize and extend its functionality to fit their specific needs. Its quick deployment timeline—live within a day—means minimal setup time and fast realization of benefits. Additionally, the tool supports seamless integration into existing LLM infrastructure, making it adaptable for various environments and use cases. Weave Router is best suited for businesses, startups, and developers who utilize multiple LLMs or rely on high volumes of AI-driven text generation, natural language understanding, or conversational AI. It is particularly valuable for teams looking to optimize their AI budgets while maintaining consistent output quality. Use cases include customer support automation, content generation, data analysis, and any scenario where LLM inference costs can quickly escalate. By routing prompts to the most cost-effective model, organizations can scale their AI usage sustainably without sacrificing performance. Regarding pricing, Weave Router is open source, which means there are no licensing fees to use the software itself. Users only pay for the underlying LLM API calls or infrastructure costs associated with the models they choose to route to. This model allows for maximum cost control and transparency. Since it is open source, there are no proprietary pricing tiers, making it accessible to a wide range of users from individual developers to large enterprises. Compared to alternatives, Weave Router stands out due to its open-source nature and its focus on cost optimization through intelligent prompt routing. While many LLM management tools focus on monitoring or analytics, Weave Router actively reduces costs by selecting the cheapest capable model for each prompt. This dynamic routing approach is more proactive and financially beneficial than static model selection or manual cost management. Its rapid deployment capability also gives it an edge over more complex or proprietary solutions that require lengthy integration. However, there are some considerations to keep in mind. Since Weave Router depends on the availability and capability of multiple LLMs, its effectiveness relies on having access to a diverse set of models with varying cost and performance profiles. Organizations without multiple model options may not realize the full cost savings. Additionally, while the tool maintains output quality by routing to capable models, there may be edge cases where subtle differences in model behavior could affect results. Users should thoroughly test and validate the routing configurations in their specific context. Lastly, as an open-source project, support and updates depend on the community and maintainers, which may require some technical expertise to manage effectively. In summary, Weave Router is a powerful, cost-saving tool for managing LLM inference expenses through smart prompt routing. Its open-source availability, rapid deployment, and significant cost reduction potential make it an attractive choice for anyone looking to optimize their AI model usage without compromising quality.
常见问题
What is Weave Router?
Weave Router is an open-source tool that reduces large language model inference costs by intelligently routing each prompt to the cheapest model capable of handling the task, maintaining output quality while optimizing spending.
How much does Weave Router cost?
Weave Router itself is free and open source. Users only pay for the underlying LLM API usage or infrastructure costs of the models they route prompts to, enabling significant cost savings on inference expenses.
Who is Weave Router best for?
It is best suited for developers, startups, and businesses that use multiple large language models or have high volumes of LLM inference, and want to reduce costs without compromising quality.
What are the main features of Weave Router?
Key features include dynamic routing of prompts to the cheapest capable model, 30-60% reduction in LLM inference costs, open-source availability, and the ability to deploy live within a day.
Does Weave Router offer a free trial?
As an open-source tool, Weave Router is free to use without a trial period. Users can deploy and test it immediately with no licensing fees.
What integrations does Weave Router support?
Weave Router integrates with various large language models and can be incorporated into existing LLM workflows and infrastructure, though specific integrations depend on user configuration and environment.
How does Weave Router work?
It works by analyzing each prompt and routing it to the least expensive model that can handle the task effectively, ensuring cost efficiency while maintaining the same output quality.
社交媒体
使用工具评价
暂无评价。成为第一个分享使用体验的人。