

这是您的 AI 工具吗?立即认领。
验证所有权、管理资料,并解锁增长功能。
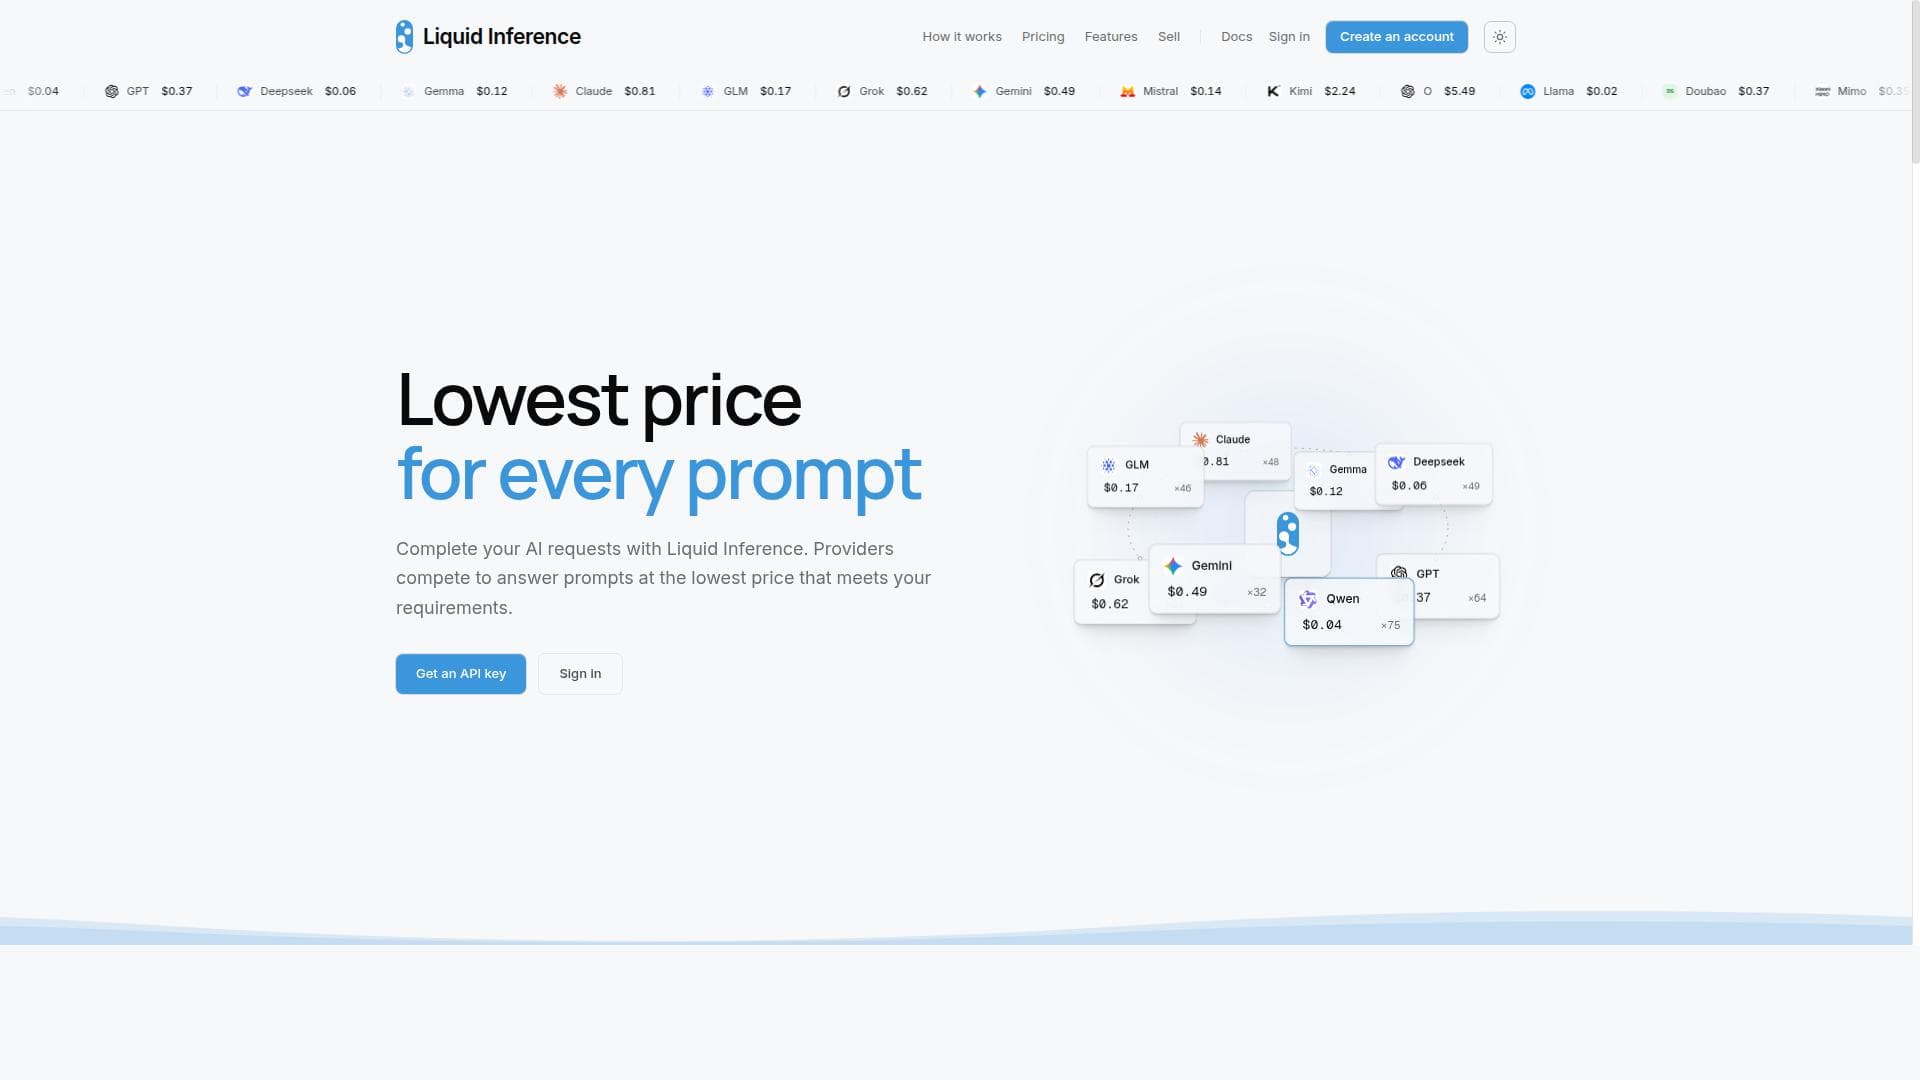
Liquid Inference revolutionizes AI usage by aggregating multiple providers and enabling real-time price competition for every AI request, ensuring users always pay the lowest price that meets their criteria. Ideal for developers and businesses seeking cost-efficient, flexible access to a wide range of AI models, it streamlines AI procurement and maximizes value.
描述
* Fully compatible with agentic coding tools: Claude Code, Codex, OpenCode, Cursor, Pi, Cline, and many more. Full multi-modal support. * Hundreds of open- and closed-weight models. Create routing rule presets or use our Auto routing algorithms. * Providers compete dynamically on price for every prompt, offering the lowest marginal cost. * Sign up for free with email, first 500 users get $20 of free inference. Receive 20% of referred fees as free inference, 10% for second-level referrals.
详细描述
Liquid Inference is an innovative AI platform designed to optimize the cost efficiency of AI prompt usage by aggregating multiple AI providers and enabling them to compete on price for every AI request. Its core purpose is to ensure that users pay the lowest possible price for AI services that meet their customized rules and requirements. By acting as a marketplace and price comparison engine for AI models, Liquid Inference empowers developers, businesses, and AI enthusiasts to access a broad range of AI capabilities without overpaying or being locked into a single provider's pricing structure. At its heart, Liquid Inference aggregates a diverse set of AI providers and models, including well-known names such as Qwen, OpenAI GPT, DeepSeek, Google Gemma, Anthropic Claude, Zhipu GLM, and xAI Grok. This extensive provider network allows the platform to perform real-time pricing comparisons for each AI request, dynamically selecting the most cost-effective offer that aligns with the user’s predefined rules. These rules can be customized to prioritize factors such as price thresholds, model preferences, latency requirements, or specific provider selections, giving users granular control over how their AI requests are fulfilled. Key features include the aggregation of multiple AI providers into a single interface, real-time competitive pricing for every prompt, and support for a wide variety of AI models spanning natural language processing, text generation, and other AI tasks. The platform’s ability to continuously monitor and compare prices ensures that users consistently benefit from market competition, often resulting in significant cost savings compared to using a single provider. Additionally, Liquid Inference supports customizable rules that let users tailor the selection process to their unique needs, whether that means always choosing the cheapest option, preferring certain providers, or balancing cost with performance. Liquid Inference is particularly well suited for developers, startups, and enterprises that rely heavily on AI-powered applications and want to optimize their AI spending without sacrificing quality or model diversity. Use cases include AI-driven content generation, chatbot development, data analysis, research, and any scenario where multiple AI models might be leveraged to find the best balance of cost and performance. By providing a unified platform to access multiple providers, it also simplifies vendor management and integration complexity. Regarding pricing, Liquid Inference itself acts as a marketplace and does not impose fixed fees beyond the cost of the underlying AI services. Users pay the lowest offer from the competing providers that meets their rules, which can vary depending on the providers’ pricing models. This competitive pricing model can lead to substantial savings, especially for high-volume AI usage. While the platform’s website does not explicitly list subscription plans or fees, it emphasizes transparency and cost efficiency through its real-time price comparison mechanism. Compared to alternatives that tie users to a single AI provider or require manual price comparisons, Liquid Inference offers a unique value proposition by automating the selection of the most cost-effective AI service for each request. This dynamic approach contrasts with traditional fixed-rate or tiered pricing models and can result in better value for users who need flexibility and cost control. However, users should consider potential trade-offs such as variability in response times or differences in model outputs when switching between providers. Notable limitations include the dependency on the availability and pricing policies of third-party AI providers, which can fluctuate and impact the overall cost and performance. Additionally, while Liquid Inference supports many popular AI models, users requiring highly specialized or proprietary models not integrated into the platform may need to supplement their usage with direct provider access. Finally, as the platform aggregates multiple providers, users should carefully configure their rules to balance cost savings with quality and latency requirements to ensure optimal results. In summary, Liquid Inference is a powerful and cost-efficient AI platform that leverages market competition among multiple AI providers to deliver the lowest price for every AI prompt. Its extensive provider support, customizable rules, and real-time pricing comparisons make it an excellent choice for users seeking to optimize AI costs without compromising on access to diverse and high-quality AI models.
工具功能
- Aggregates multiple AI providers to compete on price
- Ensures lowest cost for every AI prompt
- Supports various AI models including Qwen, OpenAI GPT, DeepSeek, Google Gemma, Anthropic Claude, Zhipu GLM, xAI Grok
- Real-time pricing comparison for AI requests
- Customizable rules to select offers
- Supports a wide range of AI models and providers
描述
Liquid Inference revolutionizes AI usage by aggregating multiple providers and enabling real-time price competition for every AI request, ensuring users always pay the lowest price that meets their criteria. Ideal for developers and businesses seeking cost-efficient, flexible access to a wide range of AI models, it streamlines AI procurement and maximizes value.
* Fully compatible with agentic coding tools: Claude Code, Codex, OpenCode, Cursor, Pi, Cline, and many more. Full multi-modal support. * Hundreds of open- and closed-weight models. Create routing rule presets or use our Auto routing algorithms. * Providers compete dynamically on price for every prompt, offering the lowest marginal cost. * Sign up for free with email, first 500 users get $20 of free inference. Receive 20% of referred fees as free inference, 10% for second-level referrals.
详细描述
Liquid Inference is an innovative AI platform designed to optimize the cost efficiency of AI prompt usage by aggregating multiple AI providers and enabling them to compete on price for every AI request. Its core purpose is to ensure that users pay the lowest possible price for AI services that meet their customized rules and requirements. By acting as a marketplace and price comparison engine for AI models, Liquid Inference empowers developers, businesses, and AI enthusiasts to access a broad range of AI capabilities without overpaying or being locked into a single provider's pricing structure. At its heart, Liquid Inference aggregates a diverse set of AI providers and models, including well-known names such as Qwen, OpenAI GPT, DeepSeek, Google Gemma, Anthropic Claude, Zhipu GLM, and xAI Grok. This extensive provider network allows the platform to perform real-time pricing comparisons for each AI request, dynamically selecting the most cost-effective offer that aligns with the user’s predefined rules. These rules can be customized to prioritize factors such as price thresholds, model preferences, latency requirements, or specific provider selections, giving users granular control over how their AI requests are fulfilled. Key features include the aggregation of multiple AI providers into a single interface, real-time competitive pricing for every prompt, and support for a wide variety of AI models spanning natural language processing, text generation, and other AI tasks. The platform’s ability to continuously monitor and compare prices ensures that users consistently benefit from market competition, often resulting in significant cost savings compared to using a single provider. Additionally, Liquid Inference supports customizable rules that let users tailor the selection process to their unique needs, whether that means always choosing the cheapest option, preferring certain providers, or balancing cost with performance. Liquid Inference is particularly well suited for developers, startups, and enterprises that rely heavily on AI-powered applications and want to optimize their AI spending without sacrificing quality or model diversity. Use cases include AI-driven content generation, chatbot development, data analysis, research, and any scenario where multiple AI models might be leveraged to find the best balance of cost and performance. By providing a unified platform to access multiple providers, it also simplifies vendor management and integration complexity. Regarding pricing, Liquid Inference itself acts as a marketplace and does not impose fixed fees beyond the cost of the underlying AI services. Users pay the lowest offer from the competing providers that meets their rules, which can vary depending on the providers’ pricing models. This competitive pricing model can lead to substantial savings, especially for high-volume AI usage. While the platform’s website does not explicitly list subscription plans or fees, it emphasizes transparency and cost efficiency through its real-time price comparison mechanism. Compared to alternatives that tie users to a single AI provider or require manual price comparisons, Liquid Inference offers a unique value proposition by automating the selection of the most cost-effective AI service for each request. This dynamic approach contrasts with traditional fixed-rate or tiered pricing models and can result in better value for users who need flexibility and cost control. However, users should consider potential trade-offs such as variability in response times or differences in model outputs when switching between providers. Notable limitations include the dependency on the availability and pricing policies of third-party AI providers, which can fluctuate and impact the overall cost and performance. Additionally, while Liquid Inference supports many popular AI models, users requiring highly specialized or proprietary models not integrated into the platform may need to supplement their usage with direct provider access. Finally, as the platform aggregates multiple providers, users should carefully configure their rules to balance cost savings with quality and latency requirements to ensure optimal results. In summary, Liquid Inference is a powerful and cost-efficient AI platform that leverages market competition among multiple AI providers to deliver the lowest price for every AI prompt. Its extensive provider support, customizable rules, and real-time pricing comparisons make it an excellent choice for users seeking to optimize AI costs without compromising on access to diverse and high-quality AI models.
常见问题
What is Liquid Inference?
Liquid Inference is a platform that aggregates multiple AI providers and models, allowing them to compete on price for every AI request. It ensures users pay the lowest offer that meets their customized rules, optimizing cost efficiency for AI prompt usage.
How much does Liquid Inference cost?
Liquid Inference does not charge fixed fees or subscriptions; instead, users pay the lowest price offered by competing AI providers for each request based on their configured rules. Pricing varies depending on the providers’ rates and usage volume.
Who is Liquid Inference best for?
It is best suited for developers, startups, and enterprises that use AI extensively and want to optimize their AI spending by accessing multiple providers through a single platform with real-time price competition.
What are the main features of Liquid Inference?
Key features include aggregation of multiple AI providers, real-time pricing comparison for every AI prompt, support for various AI models like Qwen, OpenAI GPT, and Anthropic Claude, customizable rules for selecting offers, and cost optimization through provider competition.
Does Liquid Inference offer a free trial?
The platform’s website does not explicitly mention a free trial. Users can explore the service by creating an account and testing the pricing competition mechanism, but specific trial details should be confirmed directly with Liquid Inference.
What integrations does Liquid Inference support?
Liquid Inference integrates with multiple AI providers and models including Qwen, OpenAI GPT, DeepSeek, Google Gemma, Anthropic Claude, Zhipu GLM, and xAI Grok, enabling seamless access to a broad range of AI capabilities within one platform.
How does Liquid Inference work?
Liquid Inference works by aggregating offers from multiple AI providers for each AI request and comparing their prices in real time. It then selects the lowest-priced offer that meets the user’s predefined rules, ensuring cost-effective AI prompt fulfillment.
评价
暂无评价。成为第一个分享使用体验的人。