🚀 Zaprep: Your Socials on Steroids. 免费开始 — 每月自动发送 1,000 条私信,将互动转化为潜在客户。 ,每月 1,000 条自动私信。
最新 AI 资讯
ByteDance’s new AI video generation model, Dreamina Seedance 2.0, comes to CapCut
OpenAI may be dialing back its efforts in the video generation market with theshutdown of its Sora app, but ByteDance on Thursday confirmed that its new audio and video model,Dreamina Seedance 2.0, is now rolling out in its editing platform,CapCut. ByteDance says the model allows creators to draft, edit, and sync video and audio content by using prompts, images, or reference videos. The phased rollout will begin with CapCut users in Brazil, Indonesia, Malaysia, Mexico, the Philippines, Thailand, and Vietnam, with more markets added over time. The news of the launch in CapCut follows a recent report that said themodel’s global rollout would be paused, while it worked to address intellectual property issues that drewcriticism from Hollywoodoveralleged copyright infringement.That likely explains the limited number of markets where the model is currently available within CapCut. In China, the model is available to users of ByteDance’s Jianying app. The video generation model works without reference images, even if the creator only uses a few words to describe the scene they have in mind, ByteDance says in itsannouncement. CapCut is also good at rendering realistic textures, movement, and lighting across a range of visual perspectives and angles, which the company notes could be used to edit, enhance, or correct creators’ own footage. Another use case would be allowing creators to test potential ideas based on early concepts or sketches before filming the real video. In addition, Dreamina Seedance 2.0 can be used for a wide range of content, including cooking recipes, fitness tutorials, business or product overviews, and videos with motion or action-focused content, where AI video models have historically faced challenges, the company explains. At launch, the model supports clips of up to 15 seconds long across six aspect ratios. In CapCut, the model will roll out across different areas, including editing features such as AI Video and generation tools like Video Studio. It will also come to ByteDance’s AI generation platform, Dreamina, and its marketing platform, Pippit. Given its ability to create realistic content, ByteDance says it has added safety restrictions, so the model won’t have the ability to make videos from images or videos that contain real faces. CapCut will also block the use of unauthorized generation of intellectual property. (However, if the restrictions were working properly, the model would be available now in the United States. Likely, more tweaks are still being made.) The content produced by Dreamina Seedance 2.0 will also include an invisible watermark, which will help to identify content made with the model when it’s shared off-platform, ByteDance added. This could aid in things like takedown requests from rights holders in the event that the model allowed copyright content through. ByteDance says it will partner with experts and creative communities as the model rolls out to iterate and improve upon the model’s capabilities.
View

Mistral releases a new open-source model for speech generation
French AI company Mistral released a new open-source text-to-speech model on Thursday that can be used by voice AI assistants or in enterprise use cases like customer support. The model, which lets enterprises build voice agents for sales and customer engagement, puts Mistral in direct competition with the likes of ElevenLabs, Deepgram, and OpenAI. The new model, called Voxtral TTS, supports nine languages, including English, French, German, Spanish, Dutch, Portuguese, Italian, Hindi, and Arabic. “Our customers have been asking for a speech model. So we built a small-sized speech model that can fit on a smartwatch, a smartphone, a laptop, or other edge devices. The cost of it is a fraction of anything else on the market, but it offers state-of-the-art performance,” Pierre Stock, vp of science operations at Mistral AI, told TechCrunch during a phone interview. Mistral said the new model can adapt a custom voice with a sample of less than five seconds, and also capture characteristics like subtle accents, inflections, intonations, and irregularities in the flow of speech. The model, based onMinistral 3B, can switch between languages easily without losing the characteristics of the voice, which is useful for use cases like dubbing or real-time translation. Stock said the company wanted the model to sound human and not robotic. The model has been built for real-time performance, according to the company. It has a time-to-first-audio (TTFA) — a measure of when the model starts ‘speaking’ after receiving input — of 90ms for a 10-second sample of 500 characters. The model also has a real-time factor (RTF) of 6x, which means it can render a 10-second clip in roughly 1.6 seconds. Earlier this year, Mistral launcheda pair of transcription models, one for large batch processing and the other for real-time use cases with low latency. With the new speech model, the company is likely aiming to provide a full suite of voice products to enterprises. “We plan to have an end-to-end platform that can handle multimodal streams of input, including audio, text, and image and output as well. The main benefit of that is you get way more information with an end-to-end agentic system that supports audio as an input or output,” Stock said. Mistral’s positioning is that its open source and customization bit will help enterprises adopt its voice models over competitors, as they can tune it the way they want.
View

Accenture, Anthropic Launch Cyber.AI to Expedite Cybersecurity Operations
The solution automates complex cybersecurity processes, protecting expansive digital environments without adding manual effort.
View

Humanoid Escorts Melania Trump, Greets Leaders in Bengali at White House Summit
In her address, the US First Lady urged governments and educators to adopt AI in education.
View

Namma Yatri Parent Moving Tech Acquires Automicle to Expand Zero-Commission Mobility Model into Europe
The deal extends MTI’s community-led mobility model internationally, reinforcing its vision of open, city-first infrastructure for sustainable urban transport and driver dignity.
View

Agentic AI Could Change Software Engineering Forever
Instead of developers writing every line of code, they now provide high-level specifications. AI agents take over from there.
View
Apple Has 'Complete Access' to Google's Gemini Model; Can Create Smaller Models via Distillation: Report
Apple has been granted full access to Google's Gemini model, which allows the iPhone maker to do more with the AI model used on Android smartphones, according to a report. The Cupertino company will be able to use the Gemini AI model for distillation in its own data centres, which means it can create smaller models that can be used for specific purposes. These models could be more efficient, would run on a user's device, and would not require access to the internet.
View
Yann LeCun Builds a World Model That Runs on a Single GPU
LeWorldModel can plan up to 48 times faster than some existing world models while maintaining competitive performance.
View
Infosys Announces FY26’s Largest Acquisition at $465 Mn; Total Deals Reach 5
The company has also acquired Stratus, extending the spree that includes Versent, MRE Consulting and The Missing Link.
View
Invention Engine Rewrites the Accelerator Playbook for Deep Tech
With smaller cohorts and operator-led guidance, the accelerator pushes founders to engage deeply with market realities rather than relying on theoretical frameworks.
View
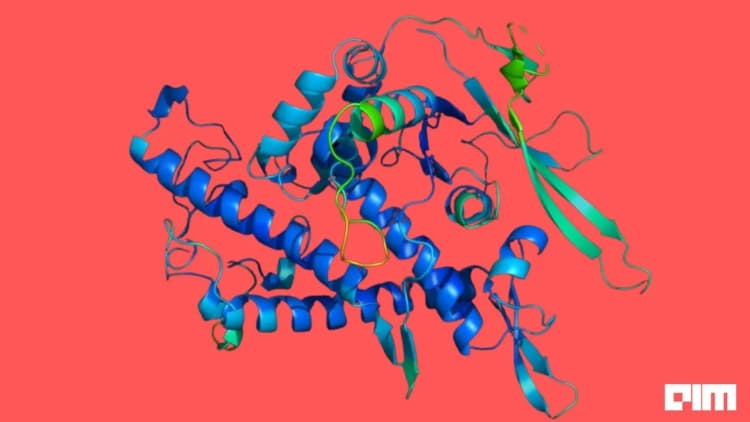
How AlphaFold is Driving India’s Life Sciences Industry
This allows companies like GSK and Sanofi to speed up R&D by 30-40 per cent, enabling faster identification of drug targets
View
How Google Used High School Math to Deliver 8x Performance Boost on NVIDIA H100s
“All you had to do was pay attention to the polar coordinates lecture in [trigonometry], and you could have discovered a 6x reduction in KV cache memory.”
View