🚀 Zaprep: je socials on steroids. Start gratis — automatiseer 1.000 DM's/maand en zet engagement om in leads. met 1.000 geautomatiseerde DM's/maand.
Dien je tool in
PoweredByAI.app is een AI-toolsdirectory die individuen, bedrijven en creators helpt de beste AI-tools te ontdekken voor schrijven, coderen, design, productiviteit en meer.
© 2026 , Een product van011BQ. Alle rechten voorbehouden.

The agreement covers low Earth orbit constellations, satellite platforms, series production, and human spaceflight infrastructure between India and Europe.
View

For GCC leaders, standardising the IST changes both infrastructure and organisational priorities.
View

Immigrants in the US are heavily represented in several low-skilled occupations. However, replacing humans with humanoids on the factory floor is easier said than done.
View

The United Nations is partnering with Google to develop the UN System Data Commons to bring multiple UN agencies into a machine-readable system.
View

The Federal Aviation Administration has beenstruggling to managean air traffic control shortage throughout the country. The reasons for the shortageare diverse, but the government has made it known that it’s on the lookout for innovative solutions to the problem. One of those solutions appears to be an $875 million AI software program that is expected to help air traffic controllers manage their workflows and more safely navigate flight routes. The Wall Street Journalreportsthat the FAA will soon launch SMART, which stands for Strategic Management of Airspace, Routes, and Trajectories — an automated software program designed to help streamline air traffic operations. Aone-page readouton the program describes SMART as “a cloud-based platform system that enhances existing FAA air traffic management systems.” It adds that the program uses AI to assess “airline schedules, weather, airport capacity, airspace conditions, and operational constraints to predict traffic flows and identify potential conflicts before they occur.” SMART, the product of a firm called Air Space Intelligence, will cost the government that amount over a 12-year period, the outlet writes. The software will roll out in the Washington, D.C., metropolitan area first before expanding to other regions, it says. Earlier this year, the FAAalso announceda “bold, new” hiring plan that the agency said would “erase the longstanding staffing shortage,” and the government is separately engaged in a broad effort to modernize the nation’s aging air traffic systems.
View

If AI labPrismMLisn’t on your radar yet, it should be — not because it’s raised gobs of money (it hasn’t yet, just a $22.25 million seed round), but because of the technical minds involved and the potentially industry-changing tech it’s developing. PrismML is betting that capable, high-performing, reasoning large language models don’t, in fact, have to be large. It is making reasoning models so small they can fit on PCs and smartphones. (It’s even rumoredto be in talks with Apple, though CEO Babak Hassibi declined to comment on that to TechCrunch.) On Thursday, PrismMLreleased Bonsai 2 27B, its latest in a family of models, which compresses Qwen3.8 27B, a widely used open source model from Alibaba, down to 5.9 GB. That’s small enough to fit on a PC and, possibly, a high-end smartphone. It’s a 9x to 10x reduction in memory versus the original. PrismML was founded by a group of Caltech researchers and is led by Hassibi, a Caltech professor and an expert in compression technologies. The startup also counts Ion Stoica as an adviser. Stoica is a co-founder of Databricks (and other companies) and the director of Berkeley’s famed Sky Computing Lab, which has birthed many technologies and startups, fromLettatoSGLang. PrismML is also backed by investors Khosla Ventures, Cerberus Capital, and Caltech. This startup is certainly not the only company working on LLM compression tech. Multiverse Computing, founded by a well-known professor from Spain’s Donostia International Physics Center, is another. (And Multiverse Computinghas raised gobs of cash.) But Hassibi says that PrismML’s compression tech is unique because its LLMs have lost virtually no performance compared with the originals. Bonsai 2 matches 98% of Qwen’s aggregate benchmark scores. That’s up from the first Bonsai, released a couple of months ago in March, that matched 95%. That original model has already been downloaded over 11 million times, and PrismML’s even smaller models have been downloaded another 2.6 million times, the company says. So this shows that PrismML’s compression results have improved from one release to the next. Whether it could ever get to 100% benchmark performance parity is a question that remains to be seen. Compression will likely always havesomeimpact, Hassibi says. Still, perfect benchmark parity is fairly academic anyway. LLMs are not so accurate in their uncompressed form, and benchmarks not so perfectly reflective of actual tasks, that a 2% degradation would likely meaningfully affect how a model performs in actual use. (Plus, the surrounding software — the harness a model runs inside of —matters a lot when it comes to accuracy, too.) PrismML says it achieves this by shrinking the “weights” that make up a model — weights are, essentially, the information a model learns and stores during training. Normally, each weight requires 16 bits. PrismML’s approach, called “ternary” weights, simplifies that down to three: +1, −1, or 0. With far smaller values to store for each weight, the model takes up dramatically less space. (For a deeper dive on the compression technique, here’s the project’sHugging Face page.) The startup’s next goal is to apply this compression technique to even bigger models. “The next models that we will release, hopefully in the next couple of months, will be in the several-hundred-billion-parameter range, and I expect it will be easier to retain the intelligence there,” Hassibi told TechCrunch. As model size grows, he added, “There is more room to be able to compress them without losing the intelligence. So I would just say, as a general trend, for larger models, it’s easier to get to 100%.” Stoica tells us that he’s excited for this tech because it’s making it possible for advanced models to run on users’ devices. “You are going to have intelligence at your fingertips, and it’s going to be free because it’s going to run on the device you already bought. It’s also going to be private, because you’re not going to send it to the cloud.”
Google and Google DeepMind researchers launched the DeepMind Institute on Wednesday to advance the conversation around artificial general intelligence (AGI). The institute lists DeepMind co-founder Shane Legg, Google executive James Manyika, and Google DeepMind chair Demis Hassabis as directors, with Legg serving as managing editor. The new institute aims to surface differing views between Google, Google DeepMind, and the broader global research community around AGI. “They will not always agree, and they will likely change their minds, as more data and information comes to light at the fast-moving frontier,” the announcement read. The inaugural collection of four essays covers a range of topics: economic policies for managing potential AGI disruption, preserving human-readable model reasoning, principles for human flourishing, and a framework for evaluating frontier AI models. Oneessay, by DeepMind safety researchers Rohin Shah and Anca Dragan, argues that AI’s shrinking window of transparency — the ability to see and check a model’s step-by-step reasoning — is not inevitable. As new architectures make the most powerful modelsharderto monitor, the authors say developers and regulators should confront the safety trade-offs directly. That could mean limiting “opaque serial depth”— the amount of sequential computation a model can perform without producing a readable reasoning trace — or requiring developers to demonstrate that less transparent systems remain just as monitorable. In anotheressay, Hassabis proposes a U.S.-led frontier AI standards body to evaluate the most advanced AI models. Under his framework, developers would initially submit models voluntarily for review up to 30 days before release. Once the evaluation system has proved effective, passing its tests could become a requirement for deploying frontier models in the United States. The body would at first design assessments in consultation with AI companies but would eventually develop independent, undisclosed evaluations — what the essay calls “held-out” tests — to prevent labs from tailoring their models to known evaluations. Hassabis said the framework could be “ratcheted up if the seriousness of the situation demands,” potentially including a coordinated slowdown among frontier AI developers. The essays arrive as the industry’s safety debateshiftsfrom broad statements of concern toward concrete proposals for disclosure, outside scrutiny, and, if safeguards fall behind, coordinated slowdowns. That shift accelerated this week as industry leaders endorsed elements of Anthropic CEO Dario Amodei’scallto “pace” frontier AI development.

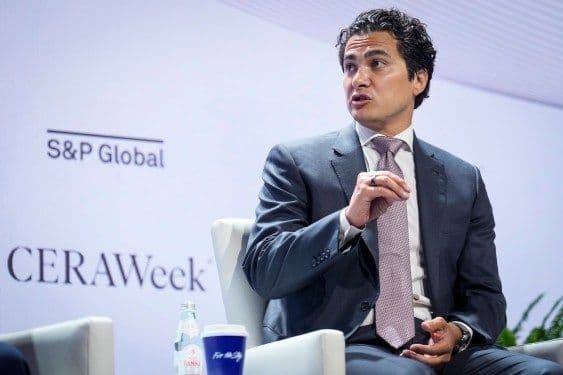
Data center developer Crusoe said Thursday it raised $3.9 billion in a Series F round that pushes its valuation to $30.9 billion. The massive round was co-led by Atreides Management, Mubadala Capital, and Valor Equity Partners. Founders Fund, GIC, Nvidia, Qatar Investment Authority (QIA), Radical Ventures, and TPG also participated, according to Crusoe. Crusoe also announced threenew board members, including Cloudflare CFO Thomas Seifert; Bill Stein, partner and CIO at Primary Digital Infrastructure; and Redwood Materials founder and CEO JB Straubel, who also sits on Tesla’s board. Straubel already has ties to Crusoe; he personally invested in the company in 2021, and Crusoe later became the first customer of Redwood’s energy storage business. The eight-year-old company’s fresh capital infusion will help finance existing data center projects, including a large site in Abilene, Texas, used by OpenAI, as well as smaller, modular AI factories that can be transported by truck and connected to large power sources almost anywhere. By manufacturing these modular data centers, called Spark, at its own facilities, Crusoe can deploy compute capacity quickly and without the need for large construction workforces. The smaller centers could also help Crusoe sidestep, at least in part, another major obstacle facing data center developers: backlash from local communities protesting massive complexes near their neighborhoods. Crusoe co-founder and CEO Chase Lochmiller, who is pictured above, said in a statement he believes AI will usher in an era of abundance, but to get there will mean “controlling the infrastructure from electrons to tokens, and we’re grateful to have investors who share that conviction.” The company makes money by leasing data center space to customers that bring their own GPUs, by renting out its own GPUs, and by selling compute power used to run AI models, known as inference. This three-pronged business model has helped make Crusoe one of the most valuable AI infrastructure companies. Crusoe recently signed amassive $13 billion, five-year cloud contract to supply quantitative trading firm Jane Street with GPUs and AI infrastructure, Bloomberg reported. The company recently met with investment bankers, including Goldman Sachs and Morgan Stanley, to discuss a potential IPO in the near future,Axios reportedlast month. The fresh fundraise comes 10 months after Crusoe raised $1.38 billion at a$10 billion valuationlast October. The company was founded in 2018 as a crypto mining operation powered by flared natural gas, but pivoted to AI infrastructure as demand for computing power skyrocketed. Crusoe’s customers include Meta, Microsoft, and Oracle.

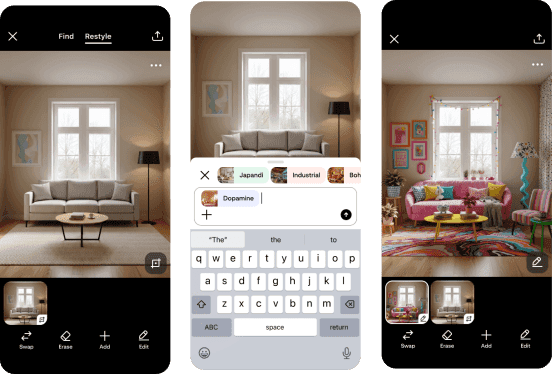
Pinterest is turning to AI to help consumers move from searching for product inspiration to actually being able to imagine what it might be like to redesign a space or compare home decor options as they’d appear in their own rooms. On Thursday, the company said it’s launching a new consumer-facing feature called “Restyle” in beta in the U.S. and Canada, powered by Pinterest Intelligence. The foundation of Pinterest Intelligence combines Nvidia Blackwell GPUs and Nvidia Dynamo with open source models and Pinterest-built technology, the companyshared on Monday. The partnership will improve the Pinterest Assistant’s ability to handle visual search requests, turn people’s searches into signals for AI discovery and shopping, and more. With Restyle, users will be able to take a photo of their space, then test and compare different options in their own homes by prompting the AI to do things like add wall art, furniture, accessories, or other home decor, including items from images they found on Pinterest, or change the lighting, paint color, plants, and more. They can also click on individual items in the room to swap them out, erase them from the image, or make further edits. Alternatively, they can ask the AI to visualize their room in a completely different style, like “bohemian,” “industrial,” “whimsical,” “dopamine,” or other trendy looks. Though it’s not a novel idea — restyling rooms has been a popular consumer use case for AI assistants — adding the feature directly to Pinterest could allow people to do more with the items they’ve saved for inspiration and design ideas. By seeing items in their own spaces, people may be more likely to buy the items they’ve saved to their boards, completing the funnel from pinning to purchase. The feature was teased at Pinterest’s annual Pinterest Presents event, where the company introduced new visual search ads, app promotion features, and other tools for advertisers. Restyle is initially available only as an early preview but will roll out more broadly next month.
View

Basetenlaunched a new safety infrastructure standard alongside its Base Labs research arm on Wednesday, partnering with Hugging Face and Goodfire AI to build safety evaluation and monitoring infrastructure for open-weight models. The announcement lands amid debate for the safety of open-weight models — which can be made dangerous by removing their safeguards through a rising technique known asabliteration. The scale of the problem is massive: Hugging Face, which hosts open source AI models, currently lists over 6,000 abliterated models. Base Labs, the research group Baseten spun up earlier this year, will develop and publish methods for training and monitoring open models. The company is framing their future work as a “standard” for open models that is transparent and built into how models are trained and deployed, rather than bolted on afterward. “We believe openness to be an advantage for AI safety,” the company said onX. “Openness provides more visibility into the behavior of models and, most importantly, greater means of turning safety research into actionable and transparent controls than closed-source.” The companies haven’t disclosed how the partnership will work technically, though Goodfire framed the goal in a reply to Baseten’s post: “Safety must be built into open models and provided by those who serve them.” Goodfire, which specializes in opening AI’s “black box” to explain how models make decisions, is the likeliest candidate for the “built into” part. Baseten, an AI inference provider,raiseda $1.5 billion Series F in June, vaulting its valuation to $13 billion. Partner Goodfire AI is similarly well-capitalized, having raised a $150 million Series B led by B Capital earlier this year to advance its model interpretability platform. Looking ahead, Baseten is putting out an open call to the broader developer ecosystem to contribute to the framework. “Together, we are building an ecosystem of open models that are safe and accessible to all,” the company noted.
View

King Charles hosted a private summit Thursdaywith some of the most prominentnames in AI and the U.K. government, including Nvidia’s Jensen Huang, leaders from OpenAI and Anthropic, the U.K.’s new AI minister Kanishka Narayan, and even the head of the U.K.’s foreign intelligence service. Paolo Benanti, who advises the pope on AI, was also there. The king’sremarks at the summit— held at Dumfries House, an 18th-century Ayrshire estate owned by King Charles’s charitable foundation — were notable because the royal family is usually careful, for constitutional reasons, about veering too deep into political issues — and AI is one of the most hot-button issues in the world right now. The king urged the leaders in the room to find a way to control AI “before it’s too late,” adding that the fast development of this technology — and its “substance” — was “both intriguing and deeply concerning.” “AI is already showing immense capacity to improve and save life,” he said, citing medicine and science as an example. “Yet those who have created these technologies are now increasingly warning that AI risks developing darker capacities, perhaps even to take life.” This remark came just days after an Anthropic researcher quit, writing online that AI companies were “racing to build machines that are much smarter than any human” and that humanity “may not survive this.” The king continued, saying it’s urgent to properly consider the “existential dangers” of what would happen if this technology fell into the wrong hands and was used in “potentially catastrophic ways.” “Surely, we need sufficient means of control before it’s all too late?” he said. As King Charles wrapped up, he urged leaders to find a way to harness the good of AI and to build international cooperation and consensus to achieve that outcome. (This remark comes after Anthropic shut off access to its Fable and Mythos models to only U.S. customers,shocking the Euro tech sceneand leaving many to think about the concept of AI sovereignty.) “The task before you is not to merely advance technology, but to ensure that it remains firmly in the service of humanity, community, and the natural world,” he said as he finished his speech. “As we embrace what is new, we must not lose what is timeless.” Outlets report thathe stayed for around 20 minutes, leaving the guests to discuss these matters among themselves. For the king’s summit, OpenAI sent its CFO Sarah Friar while Anthropic sent Tino Cuéllar, who leads global affairs. When reached for comment, Cuéllar said the company was honored to have taken part in the discussion and that it was grateful to the king for “convening industry leaders and voices from across society to discuss the role of AI in serving the public good.” This is not the first time King Charles has spoken about the challenges and benefits of AI, having done so in 2023 and 2024. This summit, however, is especially timely as AI continues to dominate every industry, topic, and form of conversation. This month, OpenAI’s Sam Altman, Elon Musk, and Anthropic’s Dario Amodei called for a deceleration in AI development, butNvidia’s Huang and President Donald Trumpquickly rejected those calls. “We’re leading China in AI,” the president said. “We’re the most sophisticated country in the world, and frankly I want to keep it that way because whoever wins AI, wins.” It shows how complex the matter has become, as the interests of Big Tech, politics, and society collide. For the past year, OpenAI and Anthropic have teased blockbuster IPOs, though OpenAI recently said its IPO plans were stalled this year as concerns over AI safety persist.

New unredacted information inthe copyright lawsuit The New York Timesbrought against OpenAI and Microsoft three years ago reveals an admission that AI scraping was tantamount to theft, and that AI products pose a major threat to publications. Per the lawsuit, a top Microsoft executive privately described the companies’ AI training practices as “theft,” and OpenAI’s own leadership said its AI models posed an “existential threat” to the publishers and journalists whose work trained them. The unsealed material also details how the companies allegedly obtained and used that content by bypassing paywalls undetected, building training datasets via mass scraping, and deliberately stripping copyright notices from training data. It’s worth noting that much of the new information comes from The Times’ own brief, not the underlying exhibits, which remain sealed. The quotes below are presented without their original context. The unredacted filing is the latest escalation in the three-year-old lawsuit, in which The New York Times initially alleged the firms violated copyright law by training generative AI models on its content. The question of whether AI firms can legally use copyrighted material to train AI has no clear answer, but judges have been largely favorable to AI companies’ arguments that training constitutes “fair use.” This legal rule lets people use copyrighted work without permission in certain cases, like parody, news reporting, or criticism. Earlier this month, theTrump administration contributed a briefin defense of OpenAI’s unlicensed use of copyrighted material to train its LLMs. Several of the new admissions, however, run counter to OpenAI’s fair use defense, particularly the rule’s requirement that use doesn’t substitute or harm the market for the original work. For example, Microsoft’s own data shows its Copilot “answer engine” caused click-through rates for The New York Times’ domain to drop as much as 93% compared to traditional Bing search. An internal Microsoft presentation written by Microsoft’s director of Applied Science, Brent Hecht, in January 2024 describes the decline as a “doom loop” that would “hurt the performance of our models and the entire web at the same time.” “It is highly unusual that an end-product threatens the economic foundations of its essential suppliers, but that is the situation we have created for our LLM business with respect to its ‘content supply chain,’” reads the Microsoft document, as quoted in the filing. Microsoft CEO Satya Nadella also testified in a deposition earlier this year that “anything that is paywalled should be licensed by anyone who wants to use it…for grounding or training,” and made clear that, if he “had been made aware that OpenAI had scraped and trained on information that was behind a paywall,” he would have “invoked [Microsoft’s right to] require OpenAI to retrain its models.” Other admissions cut against different pillars of the fair-use test: OpenAI’s head of ChatGPT, Nick Turley, wrote in internal communication that publishers face an “existential threat” from products like the chatbot, which are “largely substitutive” and “will get more and more substitutive as they get better.” OpenAI President Greg Brockman described the models as “excellent at news.” Nadella agreed under oath earlier this year that conversing with chatbots “has substituted … giving you the information right there on the website on the AI platform versus needing to go to the underlying source.” That kind of language speaks to how the technology could directly compete with, rather than transform, the original work. A Microsoft document states that there is a “real risk” that generative AI could “significantly disrupt the employment of the very people who generated the data on which the foundation model was trained.” The sheer scale of the copying is striking. The documents reveal for the first time that OpenAI’s mid-training datasets alone contain more than 91,692 copies of works published by the NYT, Daily News, and Center for Investigative Reporting. A Common Crawl-derived dataset included more than 2 million documents fromnytimes.comalone. In a January 2023 internal memo, Hecht called it “an astonishing theft of unprecedented proportions” and “the largest theft of labor in human history.” The filing lays out in new detail how OpenAI and Microsoft went about acquiring the plaintiffs’ content, including scraping it from the Bing Index. “OpenAI delivered the entire GPT-3 training dataset to Microsoft, which Microsoft used to evaluate how to implement OpenAI’s models within its own commercial products,” the filing reads. “Microsoft similarly provided training data to OpenAI through initiatives called Project Taxi and Project Mango.” The companies allegedly assembled the Project Mango data into a training dataset that contains copies of at least 160,903 unique works from the news publishers. In order to get the most out of their scraping, OpenAI employees allegedly came up with a plan to circumvent paywalls without detection. The filings show that when OpenAI researcher Nick Ryder told Brockman about a “hack to get around nytimes paywall,” Brockman replied: “ah nice.” OpenAI employees also allegedly built training datasets like WebText and WebText2 that disproportionately relied on scraped news content. They also allegedly pulled millions of articles from Common Crawl, a free, open repository of web crawl data. The findings also describe deliberate efforts to strip copyright notices from training data before it reached the model, since researchers “wouldn’t want model outputting” “copyright notices” to users. OpenAI and Microsoft did not return requests for comment.
View
View
View
View
View