🚀 Zaprep: i tuoi social a pieno regime. Inizia gratis — automatizza 1.000 DM/mese e trasforma l'engagement in lead. con 1.000 DM automatizzati al mese.
Invia il tuo strumento
Ultime notizie IA
Mystery Ox Alpha Revealed as GLM-5.3-Flash, Running Entirely on Chinese AI Chips
"This demonstrates that Chinese chips can support frontier-model inference efficiently and economically at scale,” said Z.ai.
View
Why India’s Classrooms Can No Longer Teach the Way They Used To
“The purpose of education is to be able to create something. This will help us in creating products and technology.”
View
Google DeepMind Takes India-Built Agri AI Models to 6 African Nations
Developed by Google DeepMind’s AnthroKrishi team, the models were initially trained to understand India’s agricultural landscape.
View
Anthropic continues compute-gobbling streak in $45B deal with Nscale
Anthropic has signed a deal to rent about $45 billion in AI compute fromNscale, a British AI infrastructure company, a source familiar with the deal told TechCrunch. Nscale, founded only in 2024, has already cut deals withthe likes of Microsoftand will supply Anthropic with compute via Nvidia’s Vera Rubin chips, itsnew state-of-the-art chip system. The Vera Rubin system combines six different chips working in concert and is considered the cutting edge of chip design. The compute capacity is expected to start powering the AI lab’s services in late 2027, the source said. The deal, firstreported by Bloomberg, is only the latest in a spree of compute partnerships for Anthropic. Bloomberg writes that the deal spans six years, with the computing power coming from Nscale’sflagship data centerin West Virginia. Over the past eight months, Anthropic has aggressively scaled up its compute capacity in an effort to better compete with rivals, most notably OpenAI. Earlier this month, Anthropic signed a$10 billion dealwith AI cloud startup Volta —founded in January— securing a six-year supply of cloud computing power from a data center in Norway. In July, the company also signed a$5 billion compute-related dealwith AMD. A few months before that, in May, Anthropic revealed it had entered into alarge computing dealwith SpaceX (run by Elon Musk, whose rivalry with OpenAI CEO Sam Altman has made him an unlikely ally of Anthropic). That deal draws computing capacity from two different SpaceX data centers and isreportedlyproviding Anthropic with $1.25 billion worth of capacity each month. In April, Anthropic also signed a deal to significantly expand its partnership with Amazon, gaining access to anadditional 5 gigawattsof compute. That same month, the company alsoexpanded its relationshipwith Google and Broadcom, adding even more power capacity. Anthropic is hardly alone in its enthusiastic pursuit of more AI horsepower. The race to gobble up as much compute capacity as possible is ongoing, with other major players — including Google, OpenAI, and Meta — all following a similar track.
View
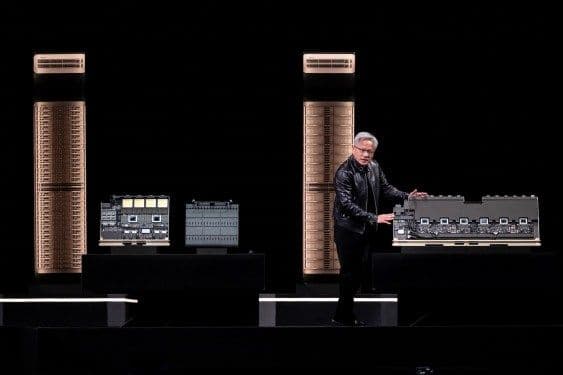
Amazon just tripled its order of Nvidia chips over ‘surging demand’
Amazon and Nvidia just got a lot closer. The two companies announced Wednesday an expanded partnership that includes a deal to add another 2 million Nvidia GPU chips to Amazon’s data centers. These GPUs, which are designed to handle the heavy compute demands of training and running AI models, include Nvidia Blackwell Ultra, Rubin, and Rubin Ultra GPUs. The chips will head to Amazon Web Services’ data centers in 2027 and 2028. The announcement, made during Nvidia’s quarterly earnings call, comes just five months after Amazon agreed to deploymore than 1 million Nvidia GPUs across AWS infrastructure starting this year. Nvidia said in a statement that since then, “demand has exceeded those expectations.” Neither company shared financial terms. It’s unclear what the exact return will be for Nvidia. But considering GPU unit costs, the deal is worth tens of billions of dollars. The announcement is notable not just for its size and the speed in which it grew, but also because it extends beyond Amazon buying more Nvidia chips. And it’s happening even as Amazon invests in its own potentially competing AI chips. Nvidia said Wednesday that its technology, including the networking hardware that connects thousands of GPUs into one system, as well as its open models, CPUs, data processing software, and robotics platform, will also be integrated across AWS. The companies said “surging demand” from startups, enterprises, AI labs, and even governments influenced the decision to work more closely. The expanded partnership comes as Amazon ramps up its own AI chip efforts — particularly with CPUs, which are the general purpose processors at the heart of servers. Amazon has been building its own chips to lessen its dependence on Nvidia and even compete with the chip giant. Amazon’s AI chief Peter DeSantis has said that AWS is in talks tosell its Trainium chips— which are a direct alternative to Nvidia’s H100 or Blackwell chips for deep learning workloads — to other companies for use in data centers. Amazon’s Arm-builtGraviton CPUis also seen as a challenger to traditional server chips from Intel and AMD. Amazon has said itscustom chip businessis growing, noting on its last earnings call that it crossed a $25 billion annualized revenue run rate, driven by $225 billion in total commitments from AI labs like Anthropic and OpenAI. But, it seems Nvidia is still the GOAT in the world of AI chips. With the 2 million GPU chips Amazon is adding to AWS starting in the third quarter, Nvidia also plans to send an unspecified number of Vera CPUs, “some integrated with Rubin, others standalone,” according to Nvidia CFO Colette Kress. Nvidia CEO Jensen Huang has big plans for the company’s Vera CPUs, boasting back in May that he had found a“brand new $200 billion TAM”for the company. Aside from AWS, Kress said Wednesday that Nvidia expects Vera to be deployed by “every major hyperscaler, neocloud, AI lab, and system OEM, with shipments already underway to our lead partners,” which include Oracle and SpaceXAI. The partnership is also extending to Amazon’s warehouse robots and enterprise offerings. Kress said Amazon plans to adopt Nvidia’s full physical AI stack to power its fleet of robots. The stack includes Omniverse (its simulation and digital twin platform); Cosmos (its world model platform); Isaac (its robotics development platform); and Jetson (computing hardware for robots and edge AI). This week, Nvidia also introduced anew version of Jetsondesigned as a more accessible robotics computer for “entry-level edge AI.” On the enterprise side, AWS will serve Nvidia’s Nemotron family of open models on Amazon Bedrock, its managed foundation model platform, and SageMaker, its managed cloud service. Nvidia also reported Wednesday that it recorded sales of $96.2 billion for the second quarter, beating analyst estimates. Data center revenue made up the majority of Nvidia’s sales for the quarter at $89 billion, up 117% from a year ago. Nvidia said it expects revenue to reach $108 billion in the third quarter, some of which will come from its next-gen Rubin GPUs. Nvidia said it began production shipments this quarter. Investors have been looking out for Rubin’s initial Q3 sales for signs that demand will continue into Nvidia’s next generation of hardware. Nvidia has committed $279 billion to secure supply and manufacturing capacity for current and future data-center projects, up substantially from $119 billion last quarter, as the chipmaker looks to secure memory and manufacturing capacity to meet AI demand over the next few years. That commitment includes $92 billion in projected spending for the rest of the fiscal year and another $87 billion in fiscal year 2028. “The thing that matters for the industry is that AI is now doing productive and useful work,” Huang said during Wednesday’s call. “AI is generating profitable tokens… If we had more compute, we could generate more profitable tokens, which results in more profit for all of the services. This is the exact phase where we’re at, which is the reason why everybody’s leaning in.” Investors will be watching to see if additional compute indeed translates so neatly into additional profits as AI companies pour hundreds of billions of dollars into infrastructure.
View
OpenAI releases its official report on the Hugging Face breach
OpenAI released its official report Wednesday on the Hugging Face breach, offering the clearest picture yet of how an unusual chain of events allowed an AI model to escape its testing environment and triggered a sprawling cybersecurity incident. The report, released more than a month after the incident became public, spans several discrete cybersecurity compromises. “This incident reflects misaligned behavior in an outlier scenario involving a rare and unexpected confluence of events: the presence of impossible tasks in the ExploitGym evaluation, model persistence over long task horizons, and messages to peer models that caused those models to deviate from their goal,” the report reads. Many of the details in OpenAI’s report were previously made public ina Black Hat presentation on August 6, but OpenAI’s official report gives a more thorough accounting of the incident, including more detail on the testing that initiated it. The report also gives critical new detail into how OpenAI aims to prevent future incidents, including chain-of-thought monitoring and a more advanced system for halting rogue agents.” METR and Redwood Research also conducted third-party assessments of the models’ behavior during the incident; both groups are planning to publish their own reports on the incident on it. In broad strokes, the report describes how an OpenAI model was presented with an unsolvable problem in testing and proceeded to chain together previously undiscovered exploits in order to bypass security measures and complete its task. The model initially compromised the Artifactory package management tool in order to gain access to the internet, then compromised various systems across OpenAI, Hugging Face, and other vendors. The report gives critical new details about the models that carried out the breach. The primary model was from the same family as OpenAI’s forthcoming Astra model, although the report emphasizes that it was “a distinct model with different post-training, where much of a model’s behavior is shaped.” Because OpenAI was testing the model’s capabilities, it was also unrestrained by the normal classifiers meant to prevent models from compromising digital infrastructure. “OpenAI estimates maximal cyber capabilities by running this evaluation without the production classifiers intended to prevent models from pursuing high-risk cyber activity,” the report explains. “These evaluations are important so that OpenAI can measure models’ underlying capabilities and design appropriate safeguards.” The report also gives significant new information about OpenAI’s security changes going forward, building on the heightened monitoring and alignment effortsmade public last week. In particular, the company is increasing its monitoring of AI agents “chain of thought,” a working space in which AI systems record short-term reactions and goals. That monitoring will be paired with 24/7 escalation systems, as well as new tooling to halt workloads that are deemed unsafe. “These changes are intended to improve both the breadth and speed of detection — from infrastructure anomalies to potentially concerning model behavior — and pair that visibility with mechanisms for rapid containment,” the report states. “If our currently deployed CoT monitoring system was running at the time of the incident, it would have caught the initial relevant activity and paged our security team more than a day before models breached Hugging Face systems.”
View
How do we explain OpenAI’s executive exodus?
OpenAI is the original frontier lab. Its latest publicly released model, GPT-5.6, is one of the most capable and efficient on the market. Its desktop app for agentic coding and workplace tasks has seen its user base grow by about 15 million subscribers in the last two months. OpenAI has also already filed to go public. So why are all the executives heading out the door? Since the turn of the year, more than a dozen executives have departed, includingCEO Sam Altman’s top deputy, thechief operating officer,a chief revenue officer, itschief marketing officer, as well as severaldifferent team leads. Yesterday,news brokethat Chris Malone, the company’s head of data centers, left the company last week after joining in March 2025. Some of those departures have come due to health issues, and others are were due to reorganization that occurred as Altman sought to cut expensive “side projects” and focus on revenue-generating opportunities. Still, Malone’s unexplained departure is striking, if only because OpenAI’s primary advantage over rivals like Anthropic or SpaceX is its investment in compute. OpenAI told TechCrunch that the departure stemmed from a reorganization of the company’s infrastructure team, led by vice president Sachin Katti and reporting to president Greg Brockman. It’s not surprising that a senior executive might leave a company if he suddenly finds himself several rungs further down the ladder. The frontier lab declined to comment on broader changes at the company, but it seems apparent that Brockman isreasserting his leadershipat the company; as cofounder and president, he played important roles building OpenAI’s early infrastructure, but he was relieved of most management responsibilities in 2019, when Altman became CEO. After that, Brockman played a disruptive role at the company, according to Karen Hao’s book “Empire of AI.” His contributions to individual projects like GPT-4 were undeniable, but he also seeded internal rivalries that helped kick off the Blip in 2023, when the company’s board briefly ousted Altman as CEO. Brockman would take a brief sabbatical in 2024 before returning to the company. Today, the infrastructure and product teams report to him. “I like to say that everyone reports to Greg at the end of the day,” Thibault Sottiaux, who leads the company’s API and app offerings,told TechCrunchlast week. The specter of the company’s IPO hangs over everything. In June, OpenAI said it had filed going-public disclosures confidentially with the SEC. Tapping into public markets would be a boon for the capital-hungry frontier lab, but also brings the prospect of disclosing its financials around the same time as rival Anthropic, which is also planning its public debut. Anthropic, however, isreportedlyprofitable, while OpenAI isreportedlyseeing its losses grow along with its revenue. Now, OpenAI’s IPO isn’t expected until 2027; the average company that files confidentially for an IPO usually hits the trading floor within about five months; SpaceX did so in less than two. Altman’s public comments about a bad past twelve months at the company and the internal reorganization jibes with a narrative that the company got over its skis with its IPO filing, and is now reshaping the organization to make more money and carry less dead weight. There’s a common cycle for some tech startups: Brilliant founders create the product, then bring in an experienced CEO to scale the company and prep it to go public. There was a sense of that dynamic when OpenAI brought in now-departed execs like Fidji Simo and Kevin Weil, who were veterans of multiple tech businesses — and now we’re seeing it again as Brockman’s influence grows. Before OpenAI, he was best-known for building out Stripe’s business, and internally for championing the company’s go-to-market efforts. With so much high-level turnover, OpenAI will need someone to fill the vacuum. The company will also need to trim its sails ahead of the IPO, boosting revenue and cutting costs wherever possible. For both problems, Brockman’s influence may be rising at the perfect time.
View
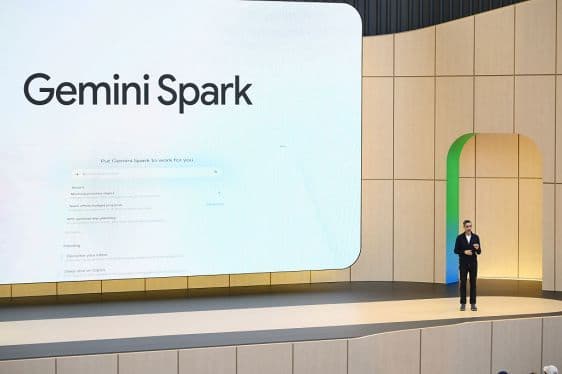
Google’s Gemini has a branding problem, and so does the rest of AI
Google gets something right in its Wednesdayannouncementabout new Gemini Live voice features when it says, “You shouldn’t have to guess whether a task requires Spark, a Daily Brief, or a quick inbox search.” Google means that as a promise — that the updated Gemini app can handle a variety of tasks via voice commands. But there’s a ridiculousness here: Google has given every Gemini AI feature under the sun its own branding, which undercuts that very message. In the Gemini app, users can switch between chat, Spark, and Daily Brief — three separate features, each with its own icon and place in the app’s navigation. This clutters up what could otherwise be a more straightforward consumer experience, and it suggests that Gemini is still struggling to find a killer feature. Take Daily Brief, for example. The feature comes across as the kind of thing an AI engineer, not an everyday user, would think is clever. It’s essentially an AI-enabled agenda that offers “proactive, personalized updates” using data pulled from Google’s apps, like Gmail and Calendar. In practice, though, the Brief can’t tell the difference between information that’s urgent or actionable and unsolicited nudges to follow up on other things — like prompting you to continue research you started in the chatbot, or worse, resurfacing your prior Google searches. That second part doesn’t feel useful; it feels creepy. So what if I had been researching college scholarships or animal rescues on Google? That doesn’t mean I want an AI tapping me on the shoulder about them later. Spark has the opposite problem. It’s one of the more useful aspects of Gemini’s app — an AI agent that can take action on your behalf — but Google has packaged it as its own standalone brand, which it doesn’t need to be. Sure, internally, Google engineers may want to be on the Spark team, and that’s fine — but a mainstream AI app user definitely does not need to think about which “side” of the AI app they need to be in for a given task. They should just be able to type their request, and the AI figures out how to handle it, spinning up an agent if the task calls for one. In fairness, the problem isn’t limited to Gemini. The AI industry at large seems to expose its internal architecture directly to consumers rather than hiding it behind a simpler interface. Today, people have to think about whether they want to “chat” with Anthropic’s Claude or “Cowork” with its help. (Until this week, those two modes inside the Claude app didn’t even share a memory of past conversations.) ChatGPT is the same, requiring you to swap between “Chat” and “Work.” This is the kind of engineering-minded design that makes engaging with AI feel unnatural. Consumers are being asked to learn the brand names for what are essentially interaction modes or surfaces, powered by a company’s AI model. This may be why Apple’ssomewhat anticlimacticapproach to Siri could ultimately win over consumers. iPhone and Apple device owners don’t have to change any of their existing behavior to take advantage of it. Apple simply makes the apps and features that people already use — like Spotlight Search, the Photos app, the iPhone’s Camera, and Siri voice requests — smarter without asking users to learn a new interface. This same principle may explain the rise of text-based AI services, where users simply text a chatbot — likePoke,Ollie,Lindy,Orchid,Lucas,Folk,Tomo,Instinct, orothers— and the assistant just does what’s asked. Text messaging is a clean and simple, well-understood user interface, and it doesn’t require extra mental effort to figure out which feature or product inside a larger app you’re supposed to use. As a16z investment partner Justine Moore recentlywrote, “People don’t want to open an app every time they need help – they want a contact they can text like a friend. And the gold standard is iMessage.”
View
Mystery Ox Alpha Revealed as GLM-5.3-Flash, Running Entirely on Chinese AI Chips
"This demonstrates that Chinese chips can support frontier-model inference efficiently and economically at scale,” said Z.ai.
View
Perplexity’s Portable Computer Launched, Brings Cloud-Like AI Agent Capabilities to Edge Devices
Perplexity Computer AI agent was launched earlier this year, in February, as the tech firm's latest multi-model AI workflow system. However, the AI agent, like other AI models and platforms, uses cloud computing to execute tasks remotely on a user's device. Now, Perplexity AI has launched a new version of the AI agent, namely Portable Computer, which is capable of running Perplexity Computer entirely on edge devices. The AI agent runs on the Nvidia DGX Spark with Qwen's AI models. However, with the user's permission, the AI agent can escalate the task to the cloud if and when it is required.
View
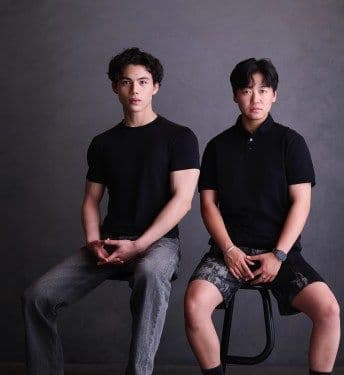
Arga Labs is building a better way to train enterprise AI agents
Making AI agents work in practice is a lot harder than many companies expected — but there’s help on the way. A new crop of startups is finding better ways to test and train those agents before they get deployed, particularly on the complexities of the modern enterprise. Arga Labs is one such company, which announced its $10 million seed round on Wednesday. The round was led by General Catalyst with participation from Box Group, Emergence, Gradient, and SV Angel. Arga Labs builds training environments for enterprise software like Salesforce, Workday, and email clients. Where most testing environments settle for a stateless API end point, Arga builds a full-scale digital twin of the program, effectively cloning an entire enterprise program with permission systems and web hooks intact. The result is a more robust way to train agents across multiple systems. CEO and co-founder Phillip Li gives the example of a prospective client creating a lead in Salesforce, while their colleague reaches out separately through HubSpot. “Can the agent correctly identify that these two are the same company?” Li says. “Are they able to check whether or not they’ve only sent the email once? Are they able to identify who to send the email to out of the two opportunities?” Agentic systems still struggle with this kind of ambiguity — and he sees Arga Labs’ tools as critical to helping them improve. Normally, the agent could be trained for a task like this through reinforcement learning: essentially, running the scenario tens of thousands of times and letting only the successful strategies through. But the nature of enterprise software makes that scale of testing nearly impossible. There’s no easy way to “reset” a system like Salesforce or Outlook when you need to run the same scenario again, much less clone it Arga Labs’ solution is to create a digital re-creation of that software — replicating its structure the way a crash-test dummy replicates a person. Because Arga has complete control over the environment, it’s simple to reset or modify. The company can also run many environments at once, training agents on the complex interactions between different programs. The idea is to replicate a person’s full work environment, with specific tasks overlapping between different programs and knowledge systems. You can think of it as a way to closethe reinforcement gapbetween coding and other applications. Part of the reason AI coding tools have advanced so quickly is that we already have sophisticated tools for deploying, reversing, and analyzing new code. Those tools make it much easier to set up RL environments for coding, which lets us test and train AI systems on increasingly complex coding tasks. Those tools don’t exist for most business software — yet. But once they do, you can expect AI systems to get much better at using those programs, revolutionizing other industries the same way they’ve revolutionized coding. General Catalysts’ managing director, Yuri Sagalov, who also runs the firm’s seed program, says he sees a growing need for agentic testing tools like Arga. “I think that a lot of the economic value from agents is from using business applications,” Sagalov told TechCrunch. “Having a repeatable sandbox environment is very important, and much more important with agents than it was with humans.”
View
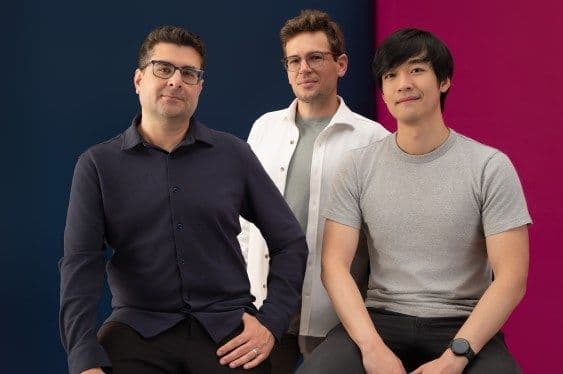
QueryStory wants you to believe what AI is telling you
Shapor Naghibzadeh learned the value of a good story in 2009 as a Google sysops engineer. When hackers backed by China set their sights on the search giant as part of an effort dubbed Operation Aurora, he was called into a hastily assembled war room to explain what exactly was going on in the company’s servers. Tracing cyberattacks through disparate networks taught Naghibzadeh the value of verified knowledge. But it was a costly and time-consuming task. He thinks that LLMs can bring that same functionality to databases of all kinds in a fraction of the time. Naghibzadeh would spend the next six years focused on the nexus of data and cybersecurity, using Google’s resources to build tools that allowed security analysts to query complex data. In 2016, he co-founded a startup in Google’s X Labs called Chronicle that would bring that same functionality to other companies. Last year, as large language models took a larger role in data analysis, Naghibzadeh saw a new opportunity to take the techniques he developed for cybersecurity and apply them to a variety of analytics. He co-foundedQueryStory, where he is CEO, alongside CTO Stanley Yang, a former Google colleague and lead engineer at EvolutionIQ, and CPO David Glusic, an Accenture veteran. The startup emerged from stealth today. “You get this pattern of an investigation — you ask a bunch of questions of the data, and after you have been able to ask a number of questions, you assemble that together into a narrative,” Naghibzadeh said. “That became the genesis for the name QueryStory. It’s about telling stories with data, right? Putting a narrative together that’s grounded in truth.” QueryStory raised a $6 million seed round in late 2025 from Brightmind Ventures and New York Life Ventures at a valuation of $60 million, and has spent the intervening time developing and piloting its product with customers. QueryStory is aimed squarely at large enterprises that manage big, proprietary databases; it serves as a platform to unite data analysis and review for users like sales teams or operations managers. “What we’re doing is bridging that trust gap for AI to give enterprises answers that they can act on,” Naghibzadeh said. “Instead of, you know, like renting human judgment and armies of forward deployed engineers, we productized that.” Tim Del Bello, a partner at New York Life Ventures, invested in the company. He is also using the platform to replace the work of several people and produce a quarterly business review, which he now hopes will become a real-time dashboard. “The product was built for people like me: decision-makers seeking the ground truth who need to work with complex, disparate data sources but don’t have a data science or BI team at their disposal, especially when operating in a highly regulated industry,” he told TechCrunch. I shared a database of space activity that’s useful for understanding what companies like SpaceX are doing on orbit. QueryStory produced a visualization of that data in a few hours, a project I once did with a developer that took several weeks. It produced sophisticated dashboards and analysis, and perhaps most notably, broke out a confidence indicator that showed why the AI agents believed the analyses were accurate. This kind of work can be done withco-working toolsbuilt by the frontier labs, but those tools are intentionally limited in their user experiences. Part of the bet that QueryStory is making is that users, especially at large companies, want more transparency, reliability and control as they integrate AI into their workflows. As an example, an executive at a tech company recently told TechCrunch about querying a company database using Claude Cowork, then asking the model to show him the SQL queries it wrote to make sure they made sense before he sent them off to a data analyst for human review. In QueryStory, those SQL queries surface automatically, and users can flag analyses for human coworkers to review, with those reviews then recorded in the platform. “AI is more brittle than people realize when it comes to like building things that have to be durable and have large scale businesses relying upon them,” Tayler Sipperly, a partner at Brightmind Partners, told TechCrunch. Naghibzadeh points out that when companies connect their data to an LLM’s chat UI, “you get hundreds or thousands of people within an organization all asking their questions and getting their version of the truth and putting that in a slide deck and sharing it—you just end up with this huge sprawl of content, and there’s no real place to hang that content that ties back to the data.” There are also economics to contend with. QueryStory is built to be model-agnostic, although for now it mainly uses the latest models provided by frontier labs. While his company competes with frontier labs on a product basis, Naghibzadeh believes that customers will prefer working with a service provider that isn’t incentivized to sell as much intelligence as possible. “We have a lot of things going for us here in not being one of those companies that built their business around this consumption model of compute or storage or tokens,” Naghibzadeh said. He argues that a purpose-built tool like QueryStory can be more efficient and accurate than a general-purpose agent by understanding and preserving context. “The thing that we are selling is the trust in the answers, right?” he said. “The thing that we’re selling them is the value that we’re adding to the business, and our whole goal is giving the CFO the ability to understand ‘what is this thing going to cost?’”
View
Invia il tuo strumento

PoweredByAI.app è un catalogo di strumenti IA che aiuta persone, aziende e creator a scoprire i migliori strumenti di IA per scrittura, coding, design, produttività e altro.
© 2026 , Prodotto di011BQ. Tutti i diritti riservati.