🚀 Zaprep : tes réseaux sociaux sous stéroïdes. Commencer gratuitement — automatise 1 000 DM/mois et transforme l'engagement en leads. avec 1 000 DM automatisés/mois.
AI NewsEmbedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says
Embedded AI evaluators won’t be an easy solution, Hugging Face’s policy chief says
7:31 AM IST · October 20, 2026
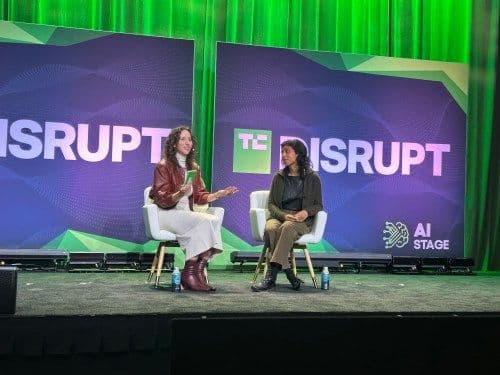
AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether one AI product is better than another. However, the methods behind these evaluations are complicated and still maturing, said Irene Solaiman, Hugging Face’s chief policy officer, during a discussion atTechCrunch Disruptlast week. Testing needs to come together into a more consistent science if the industry is to rely on them in the future. With that in mind, can we trust the current tests that are being released? “Trust is such a weighted term,” said Solaiman. “In terms of whether we can trust results, one big part [of that] is can you reproduce the results of an evaluation? Do you have the level of access that you need to the model itself — this is where open weights come in in a big way,” she added. Reproducibility in model evaluations has long remained one of thestickier aspects of benchmarking— and remains a topic of significant debate in the industry. Outside of an individual test’s validity, there’s also the added question of how that test compares to other evaluations. “They are an evolving science — where we don’t know how to meaningfully compare them to each other,” Solaiman said. “They start to get ineffective relatively quickly, and we don’t have as much of a thriving ecosystem as we need,” she added. “There’s this hunger for an embedded evaluator ecosystem now, but the qualifications that determine who is an effective evaluator across what tasks need a lot more standardization.” Theidea of embedded evaluators— in which supposedly “neutral” third-party observers are placed inside AI organizations — has been popularized over the last several months, as AI labs grapple witha rash of safety incidentsthat have spurred concerns over the potential harms of their technology. Hugging Facewas famously the targetof one of those incidents. Instead of active government regulation to identify and mitigate model safety concerns, labs have pushed for the third-party solution. However, doubts remain over how neutral or effective those evaluators will actually be. Anthropic’sdecision to hire Accentureas its first evaluator spurred a good amount of backlash, with somecritics mockingthe idea that the consulting firm was qualified to do the task at hand. Evaluations are now moving from merely a test of the model itself to a test of the entire system around the model — including the harness and agent. The harness — or the tool the user is using to access the model — specifically, has a lot to do with a model’s performance, and a weaker model with a better harness could easily outperform a frontier model, Solaiman shared. “Agentic evals are really hard and really expensive,” said Solaiman. “We have just more evaluations for models. … We don’t have as many evaluations for harnesses, and we are developing better evaluations for the holistic agent — because that’s what a lot of folks are getting value out of,” she added. In other words, the evaluation space is a bit of a free-for-all at the moment, and if benchmarking is going to continue to be seen as a useful tool for industry leaders, a more uniform, industry-wide approach — where everyone is on the same page — may be necessary.
read moreDernières actualités IA
Toutes les actualités →
Soumettre ton outil
PoweredByAI.app est un annuaire d'outils IA qui aide les particuliers, les entreprises et les créateurs à découvrir les meilleurs outils IA pour la rédaction, le code, le design, la productivité, et plus encore.
© 2026 , Un produit de011BQ. Tous droits réservés.