

¿Es esta tu herramienta de IA? Reclámala hoy.
Verifica la propiedad, gestiona tu perfil y desbloquea funciones de crecimiento.
oMLX is a native macOS inference server optimized for Apple Silicon Macs, dramatically reducing LLM response times with its innovative SSD caching and continuous batching. It’s perfect for developers and data scientists seeking efficient, low-latency local LLM deployment with seamless API compatibility for popular models like Claude Code and OpenClaw.

Descripción
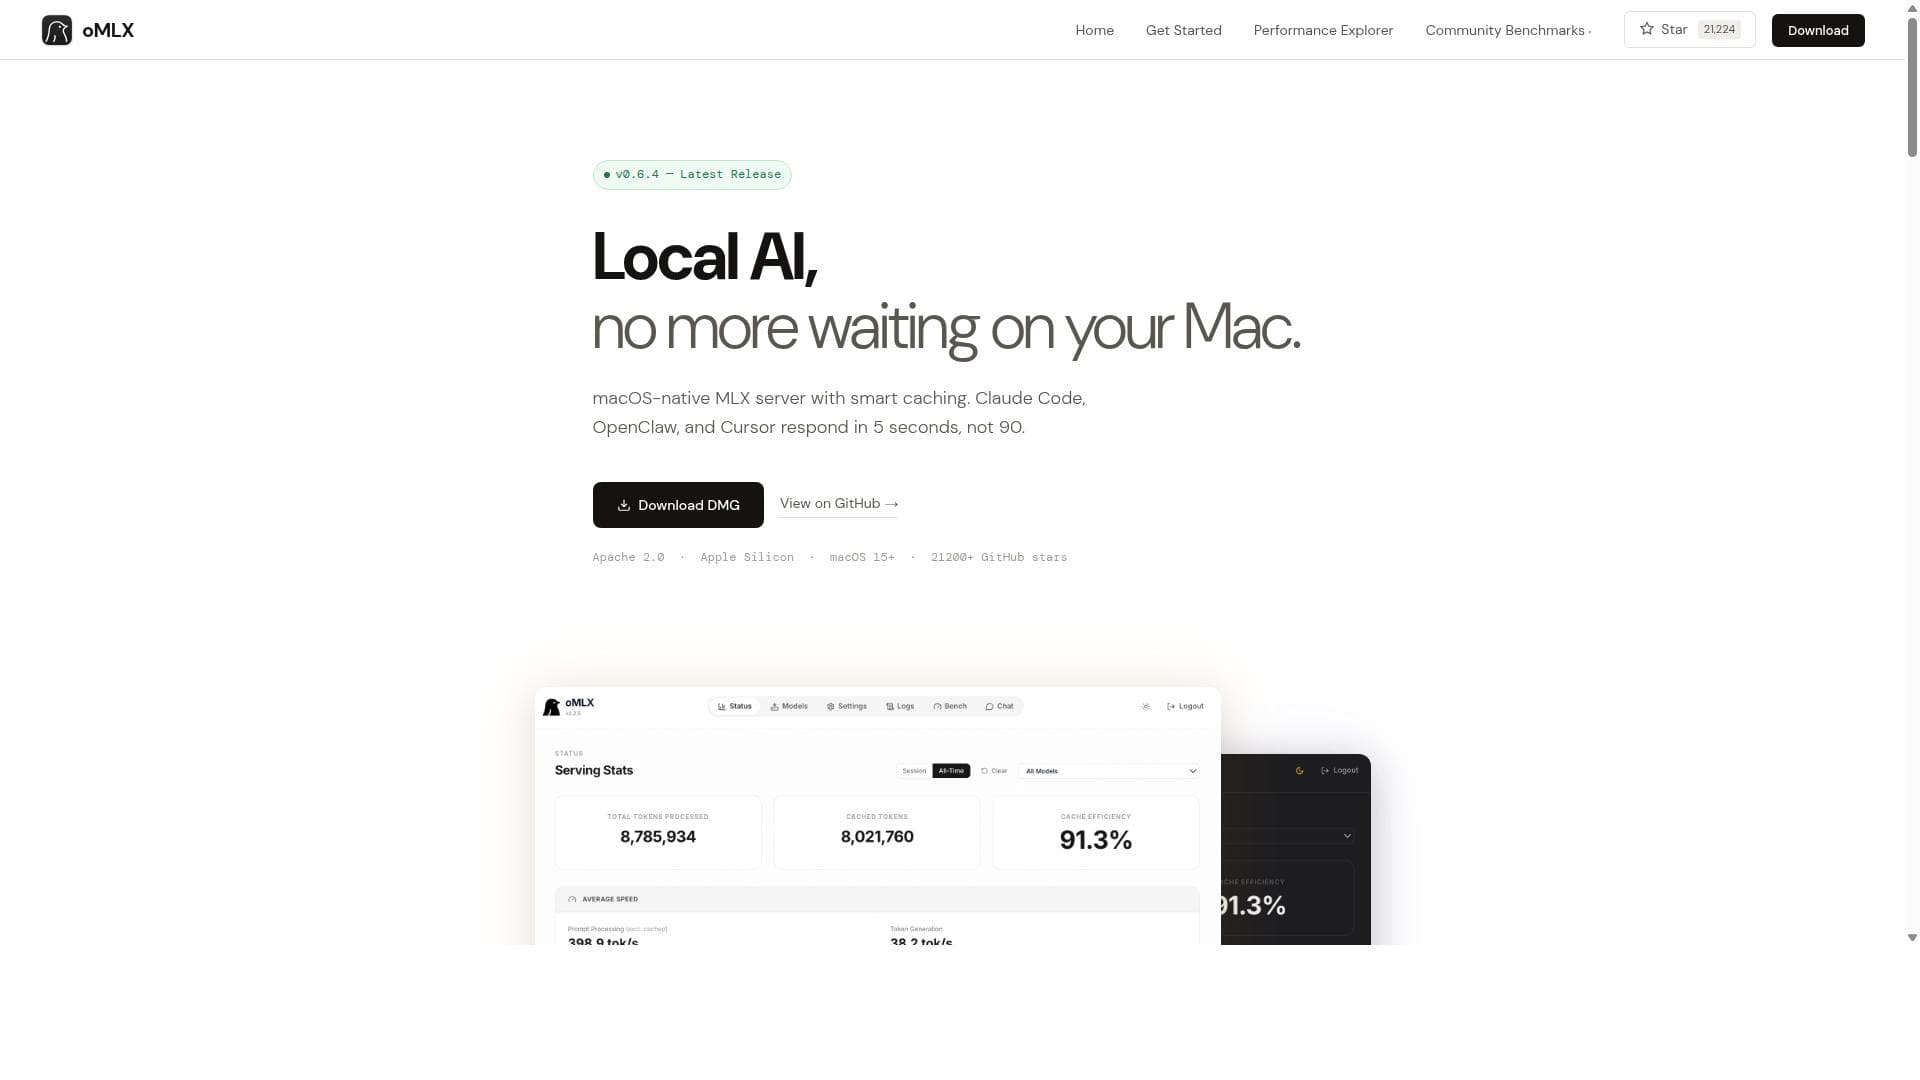
oMLX turns your Mac into a full LLM inference server, run from the menu bar. It serves text, vision, OCR, embedding and reranker models with continuous batching, plus a RAM+SSD tiered KV cache that survives restarts, so Claude Code and Cursor respond in about 5s instead of 90s. OpenAI and Anthropic compatible APIs drop straight in. Native Swift, not Electron. Apache 2.0, open source.
Descripción detallada
oMLX is a specialized native macOS inference server designed to optimize the deployment and execution of large language models (LLMs) on Apple Silicon Macs. Built on the MLX framework, oMLX focuses on delivering high-performance LLM inference by leveraging the unique hardware capabilities of Apple’s M1 and M2 chips. Its core purpose is to provide developers and data scientists with a seamless, efficient, and low-latency environment for running LLMs locally or in private environments without relying solely on cloud-based services. This makes it particularly valuable for those who prioritize data privacy, cost control, and speed in their AI workflows. One of the standout features of oMLX is its innovative paged SSD key-value caching system. This technology drastically reduces the agent time-to-first-token (TTFT), a critical metric in LLM inference that measures the delay before the model starts generating output. While traditional setups can experience TTFTs ranging from 30 to 90 seconds, oMLX’s caching mechanism cuts this down to under 5 seconds, enabling near-instantaneous responses. This improvement is crucial for interactive applications such as chatbots, coding assistants, and real-time data analysis tools. In addition to caching, oMLX supports continuous batching, which optimizes throughput by efficiently managing multiple inference requests simultaneously. This capability enhances performance in multi-user or high-demand scenarios. The platform also offers compatibility with popular APIs from OpenAI and Anthropic, making it easy to integrate with existing workflows that rely on these providers. Furthermore, oMLX provides a drop-in API compatible with models like Claude Code, OpenClaw, and Cursor, allowing developers to switch or combine models without extensive reconfiguration. oMLX is tailored specifically for Apple Silicon Macs, taking full advantage of the architecture’s efficiency and performance. This focus ensures that users with Mac hardware can deploy LLMs locally with optimized resource utilization, reducing dependency on external cloud services and associated latency or privacy concerns. The tool is ideal for developers, data scientists, and AI researchers who require fast, reliable LLM inference on macOS environments, particularly those working on applications involving natural language understanding, code generation, or AI-driven automation. Regarding pricing, oMLX’s website does not publicly list detailed pricing plans, suggesting that it may offer custom or enterprise pricing models. Interested users are encouraged to contact the oMLX team directly through their website for specific pricing information, trials, or demos. This approach often indicates a focus on professional and enterprise users rather than casual or hobbyist users. Compared to alternative LLM inference solutions, especially cloud-based APIs, oMLX stands out by enabling local inference optimized for Mac hardware. While many platforms require powerful GPUs or cloud infrastructure, oMLX leverages Apple Silicon’s unified memory and efficient cores to deliver competitive performance with lower latency and improved privacy. However, it may not support as broad a range of models or hardware platforms as some cloud providers. Additionally, the reliance on macOS and Apple Silicon limits its use to users within the Apple ecosystem. Potential limitations include the requirement for Apple Silicon Macs, which excludes users on Intel-based Macs or other operating systems. Also, since oMLX is a specialized inference server, users without technical expertise in macOS development or LLM deployment might face a learning curve. The lack of publicly available pricing and trial information may also be a barrier for some potential users. Nonetheless, for its target audience, oMLX offers a compelling solution for fast, efficient, and private LLM inference on Mac hardware.
Características de la herramienta
- Native macOS inference server built on MLX
- Paged SSD key-value caching to reduce agent TTFT to under 5 seconds
- Compatible with OpenAI and Anthropic APIs
- Supports continuous batching
- Drop-in API for Claude Code, OpenClaw, and Cursor
- Optimized for Apple Silicon Macs
Descripción
oMLX is a native macOS inference server optimized for Apple Silicon Macs, dramatically reducing LLM response times with its innovative SSD caching and continuous batching. It’s perfect for developers and data scientists seeking efficient, low-latency local LLM deployment with seamless API compatibility for popular models like Claude Code and OpenClaw.
oMLX turns your Mac into a full LLM inference server, run from the menu bar. It serves text, vision, OCR, embedding and reranker models with continuous batching, plus a RAM+SSD tiered KV cache that survives restarts, so Claude Code and Cursor respond in about 5s instead of 90s. OpenAI and Anthropic compatible APIs drop straight in. Native Swift, not Electron. Apache 2.0, open source.
Descripción detallada
oMLX is a specialized native macOS inference server designed to optimize the deployment and execution of large language models (LLMs) on Apple Silicon Macs. Built on the MLX framework, oMLX focuses on delivering high-performance LLM inference by leveraging the unique hardware capabilities of Apple’s M1 and M2 chips. Its core purpose is to provide developers and data scientists with a seamless, efficient, and low-latency environment for running LLMs locally or in private environments without relying solely on cloud-based services. This makes it particularly valuable for those who prioritize data privacy, cost control, and speed in their AI workflows. One of the standout features of oMLX is its innovative paged SSD key-value caching system. This technology drastically reduces the agent time-to-first-token (TTFT), a critical metric in LLM inference that measures the delay before the model starts generating output. While traditional setups can experience TTFTs ranging from 30 to 90 seconds, oMLX’s caching mechanism cuts this down to under 5 seconds, enabling near-instantaneous responses. This improvement is crucial for interactive applications such as chatbots, coding assistants, and real-time data analysis tools. In addition to caching, oMLX supports continuous batching, which optimizes throughput by efficiently managing multiple inference requests simultaneously. This capability enhances performance in multi-user or high-demand scenarios. The platform also offers compatibility with popular APIs from OpenAI and Anthropic, making it easy to integrate with existing workflows that rely on these providers. Furthermore, oMLX provides a drop-in API compatible with models like Claude Code, OpenClaw, and Cursor, allowing developers to switch or combine models without extensive reconfiguration. oMLX is tailored specifically for Apple Silicon Macs, taking full advantage of the architecture’s efficiency and performance. This focus ensures that users with Mac hardware can deploy LLMs locally with optimized resource utilization, reducing dependency on external cloud services and associated latency or privacy concerns. The tool is ideal for developers, data scientists, and AI researchers who require fast, reliable LLM inference on macOS environments, particularly those working on applications involving natural language understanding, code generation, or AI-driven automation. Regarding pricing, oMLX’s website does not publicly list detailed pricing plans, suggesting that it may offer custom or enterprise pricing models. Interested users are encouraged to contact the oMLX team directly through their website for specific pricing information, trials, or demos. This approach often indicates a focus on professional and enterprise users rather than casual or hobbyist users. Compared to alternative LLM inference solutions, especially cloud-based APIs, oMLX stands out by enabling local inference optimized for Mac hardware. While many platforms require powerful GPUs or cloud infrastructure, oMLX leverages Apple Silicon’s unified memory and efficient cores to deliver competitive performance with lower latency and improved privacy. However, it may not support as broad a range of models or hardware platforms as some cloud providers. Additionally, the reliance on macOS and Apple Silicon limits its use to users within the Apple ecosystem. Potential limitations include the requirement for Apple Silicon Macs, which excludes users on Intel-based Macs or other operating systems. Also, since oMLX is a specialized inference server, users without technical expertise in macOS development or LLM deployment might face a learning curve. The lack of publicly available pricing and trial information may also be a barrier for some potential users. Nonetheless, for its target audience, oMLX offers a compelling solution for fast, efficient, and private LLM inference on Mac hardware.
Preguntas frecuentes
What is oMLX?
oMLX is a native macOS inference server built on the MLX framework, designed to optimize large language model inference on Apple Silicon Macs by reducing latency and improving performance through advanced caching and batching techniques.
How much does oMLX cost?
Pricing details for oMLX are not publicly listed on their website. Interested users should contact the oMLX team directly via their website to inquire about pricing, plans, or enterprise options.
Who is oMLX best for?
oMLX is best suited for developers, data scientists, and AI researchers who use Apple Silicon Macs and need efficient, low-latency local inference for large language models, especially those focused on privacy-sensitive or high-performance applications.
What are the main features of oMLX?
Key features include a native macOS inference server optimized for Apple Silicon, paged SSD key-value caching that reduces time-to-first-token to under 5 seconds, continuous batching for handling multiple requests efficiently, and compatibility with OpenAI and Anthropic APIs as well as drop-in API support for models like Claude Code, OpenClaw, and Cursor.
Does oMLX offer a free trial?
There is no publicly available information about a free trial on the oMLX website. Prospective users should reach out to the oMLX team directly to ask about trial availability or demo options.
What integrations does oMLX support?
oMLX supports integrations with OpenAI and Anthropic APIs and offers a drop-in API compatible with models such as Claude Code, OpenClaw, and Cursor, enabling seamless integration into existing AI workflows.
How does oMLX work?
oMLX works by running a native inference server on macOS that leverages Apple Silicon hardware. It uses paged SSD key-value caching to minimize latency and continuous batching to optimize throughput, allowing fast and efficient execution of large language models locally with API compatibility for popular LLM providers.
Redes sociales
Usar herramientaReseñas
Aún no hay reseñas. Sé el primero en compartir tu experiencia.