


Ist das dein KI-Tool? Beanspruche es noch heute.
Bestätige die Inhaberschaft, verwalte dein Profil und schalte Wachstumsfunktionen frei.
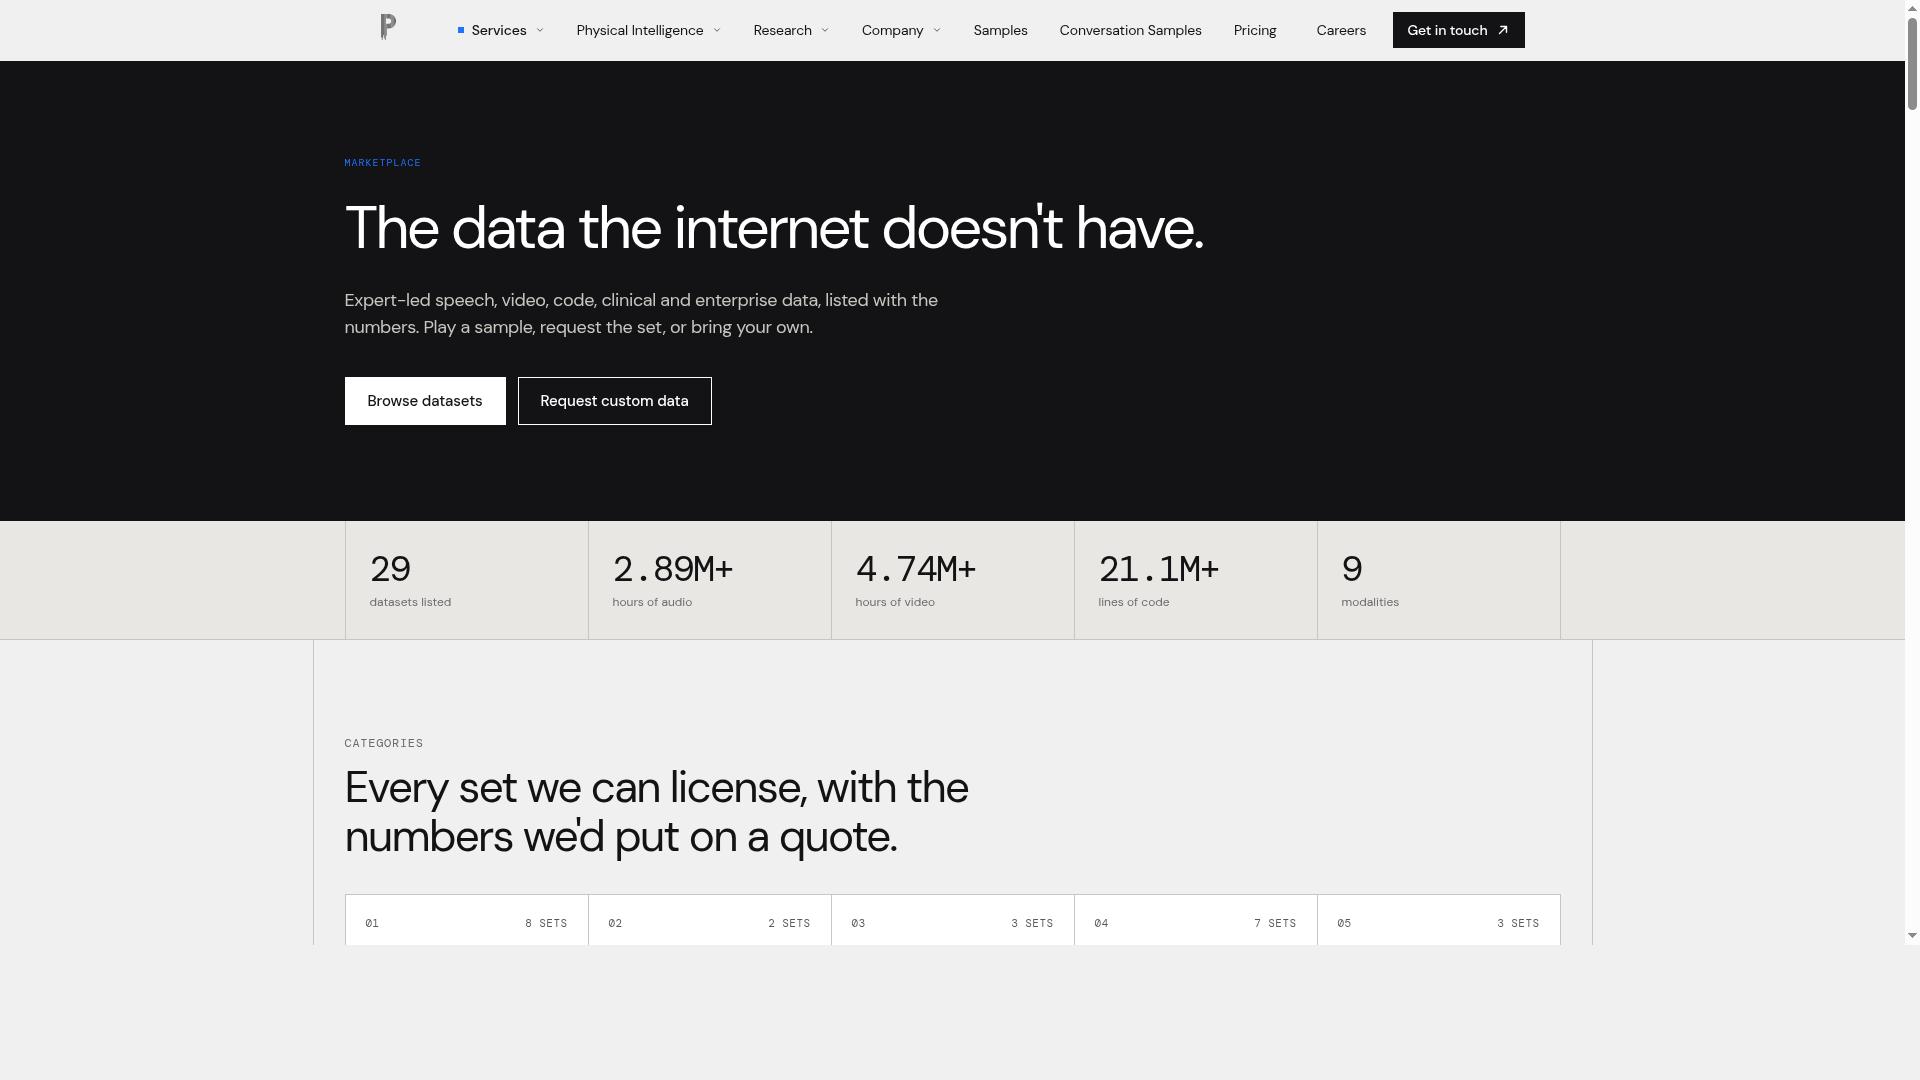
Perit is a specialized data marketplace offering 29 high-quality datasets across 10 categories, including multilingual speech, video, and reinforcement learning environments. It is ideal for AI researchers and developers seeking licensed, diverse training data to accelerate machine learning projects.
Beschreibung
Perit Marketplace turns your data and expertise into training work for frontier AI labs. Two ways in: submit data you own (audio, video, code, docs, CAD and more; 29 datasets listed so far), or build RL tasks and benchmarks on our platform using our VMs and model credits. We pitch them to labs, and approved experts scale to hundreds of tasks a week. Built by Perit (YC F26), now past $11M in revenue in 4.5 months.
Ausführliche Beschreibung
Perit is a comprehensive data marketplace designed to facilitate access to high-quality datasets for AI and machine learning development. Its core purpose is to provide organizations, researchers, and developers with a curated selection of datasets available for licensing, spanning a wide array of categories and data types. By centralizing diverse datasets in one platform, Perit streamlines the process of sourcing training data, which is often a critical bottleneck in building effective AI models. The marketplace currently offers 29 datasets across 10 distinct categories, making it a versatile resource for various AI applications. One of Perit's standout features is the breadth and diversity of its dataset offerings. It includes speech datasets covering 122 languages, making it invaluable for projects requiring multilingual speech recognition or natural language processing capabilities. Additionally, Perit offers both egocentric and general video datasets, which are essential for computer vision tasks such as activity recognition, object detection, and autonomous systems training. Beyond multimedia data, Perit also provides production codebases and agentic reinforcement learning environments, which support the development and benchmarking of AI agents in simulated settings. The inclusion of field documents and clinical cohorts further expands its utility to sectors like healthcare and scientific research, where specialized data is crucial. Each dataset listing on Perit is detailed and transparent, providing essential metadata such as volume, available formats, license status, and current availability. This level of detail helps users quickly assess the suitability of datasets for their specific needs without unnecessary back-and-forth. The licensing model ensures that users can legally and ethically utilize the data, which is a significant advantage for enterprises concerned about compliance and intellectual property rights. Perit is best suited for AI researchers, data scientists, machine learning engineers, and organizations that require reliable access to diverse and high-quality datasets. Use cases include training multilingual speech recognition systems, developing computer vision algorithms using egocentric video data, experimenting with reinforcement learning in agentic environments, and conducting clinical research with cohort data. Its wide-ranging dataset categories also make it a valuable resource for startups and enterprises looking to accelerate AI model development without the overhead of collecting and curating data themselves. Regarding pricing, Perit operates on a licensing basis for each dataset, which means costs vary depending on the dataset chosen, its volume, and the licensing terms. While specific pricing details are not publicly listed on the website, interested users can explore the marketplace to view dataset availability and licensing status, then contact Perit for tailored pricing and licensing agreements. This approach allows flexibility to accommodate different project scales and budget requirements. Compared to other data marketplaces, Perit stands out due to its focus on frontier training data types such as agentic reinforcement learning environments and production codebases, which are less commonly found in typical data marketplaces. Its multilingual speech datasets and egocentric video collections also provide unique value for specialized AI domains. However, unlike some platforms that offer open datasets or subscription-based access, Perit's licensing model may require negotiation and could involve higher upfront costs, which could be a consideration for smaller teams or individual developers. Potential limitations include the relatively limited number of datasets (29) compared to larger, more generalist data marketplaces. While the datasets are diverse and high-quality, users with very niche or uncommon data needs might find the selection less comprehensive. Additionally, the absence of publicly available pricing and the need for licensing agreements might slow down immediate access for some users. Integration details and API support are not explicitly highlighted, which could be a factor for teams seeking seamless data pipeline automation. In summary, Perit is a specialized data marketplace that excels in providing curated, high-quality datasets across multiple AI-relevant categories with a strong emphasis on licensing transparency and dataset diversity. It is particularly valuable for organizations and researchers seeking multilingual speech data, video datasets, reinforcement learning environments, and clinical cohorts. While pricing and access require direct engagement, the platform offers a robust solution for sourcing frontier training data essential for advanced AI and machine learning projects.
Tool-Funktionen
- 29 datasets available for licensing
- Covers 10 different categories including speech, video, and clinical data
- Datasets include speech in 122 languages
- Includes egocentric and general video datasets
- Offers production codebases and agentic reinforcement learning environments
- Provides detailed dataset listings with volume, formats, license status, and availability
Beschreibung
Perit is a specialized data marketplace offering 29 high-quality datasets across 10 categories, including multilingual speech, video, and reinforcement learning environments. It is ideal for AI researchers and developers seeking licensed, diverse training data to accelerate machine learning projects.
Perit Marketplace turns your data and expertise into training work for frontier AI labs. Two ways in: submit data you own (audio, video, code, docs, CAD and more; 29 datasets listed so far), or build RL tasks and benchmarks on our platform using our VMs and model credits. We pitch them to labs, and approved experts scale to hundreds of tasks a week. Built by Perit (YC F26), now past $11M in revenue in 4.5 months.
Ausführliche Beschreibung
Perit is a comprehensive data marketplace designed to facilitate access to high-quality datasets for AI and machine learning development. Its core purpose is to provide organizations, researchers, and developers with a curated selection of datasets available for licensing, spanning a wide array of categories and data types. By centralizing diverse datasets in one platform, Perit streamlines the process of sourcing training data, which is often a critical bottleneck in building effective AI models. The marketplace currently offers 29 datasets across 10 distinct categories, making it a versatile resource for various AI applications. One of Perit's standout features is the breadth and diversity of its dataset offerings. It includes speech datasets covering 122 languages, making it invaluable for projects requiring multilingual speech recognition or natural language processing capabilities. Additionally, Perit offers both egocentric and general video datasets, which are essential for computer vision tasks such as activity recognition, object detection, and autonomous systems training. Beyond multimedia data, Perit also provides production codebases and agentic reinforcement learning environments, which support the development and benchmarking of AI agents in simulated settings. The inclusion of field documents and clinical cohorts further expands its utility to sectors like healthcare and scientific research, where specialized data is crucial. Each dataset listing on Perit is detailed and transparent, providing essential metadata such as volume, available formats, license status, and current availability. This level of detail helps users quickly assess the suitability of datasets for their specific needs without unnecessary back-and-forth. The licensing model ensures that users can legally and ethically utilize the data, which is a significant advantage for enterprises concerned about compliance and intellectual property rights. Perit is best suited for AI researchers, data scientists, machine learning engineers, and organizations that require reliable access to diverse and high-quality datasets. Use cases include training multilingual speech recognition systems, developing computer vision algorithms using egocentric video data, experimenting with reinforcement learning in agentic environments, and conducting clinical research with cohort data. Its wide-ranging dataset categories also make it a valuable resource for startups and enterprises looking to accelerate AI model development without the overhead of collecting and curating data themselves. Regarding pricing, Perit operates on a licensing basis for each dataset, which means costs vary depending on the dataset chosen, its volume, and the licensing terms. While specific pricing details are not publicly listed on the website, interested users can explore the marketplace to view dataset availability and licensing status, then contact Perit for tailored pricing and licensing agreements. This approach allows flexibility to accommodate different project scales and budget requirements. Compared to other data marketplaces, Perit stands out due to its focus on frontier training data types such as agentic reinforcement learning environments and production codebases, which are less commonly found in typical data marketplaces. Its multilingual speech datasets and egocentric video collections also provide unique value for specialized AI domains. However, unlike some platforms that offer open datasets or subscription-based access, Perit's licensing model may require negotiation and could involve higher upfront costs, which could be a consideration for smaller teams or individual developers. Potential limitations include the relatively limited number of datasets (29) compared to larger, more generalist data marketplaces. While the datasets are diverse and high-quality, users with very niche or uncommon data needs might find the selection less comprehensive. Additionally, the absence of publicly available pricing and the need for licensing agreements might slow down immediate access for some users. Integration details and API support are not explicitly highlighted, which could be a factor for teams seeking seamless data pipeline automation. In summary, Perit is a specialized data marketplace that excels in providing curated, high-quality datasets across multiple AI-relevant categories with a strong emphasis on licensing transparency and dataset diversity. It is particularly valuable for organizations and researchers seeking multilingual speech data, video datasets, reinforcement learning environments, and clinical cohorts. While pricing and access require direct engagement, the platform offers a robust solution for sourcing frontier training data essential for advanced AI and machine learning projects.
Häufig gestellte Fragen
What is Perit?
Perit is a data marketplace that offers a curated selection of 29 datasets across 10 categories, available for licensing to support AI and machine learning development.
How much does Perit cost?
Perit operates on a licensing model with pricing varying by dataset, volume, and license terms. Specific pricing details are available upon inquiry through their marketplace.
Who is Perit best for?
Perit is best suited for AI researchers, data scientists, machine learning engineers, and organizations needing diverse, high-quality datasets for training AI models.
What are the main features of Perit?
Key features include 29 datasets across 10 categories, multilingual speech data in 122 languages, egocentric and general video datasets, production codebases, agentic reinforcement learning environments, and detailed dataset metadata including volume, formats, and license status.
Does Perit offer a free trial?
There is no publicly available information about a free trial. Access to datasets is managed through licensing agreements.
What integrations does Perit support?
Perit does not explicitly list integrations or API support on its website; users typically license datasets for use in their own AI and machine learning workflows.
How does Perit work?
Users browse the Perit marketplace to review available datasets with detailed metadata, then license datasets that fit their project needs, enabling legal and ethical use of high-quality training data.
Bewertungen
Noch keine Bewertungen. Teile als Erste:r deine Erfahrung.